Rich Sutton and Khurram Javed: Why AI Models Stop Learning, and How to Start It Again · 苏菲拉底
字幕 字幕位置
--:--
点击播放,这里会跟随视频显示当前句的中英字幕。

Rich Sutton and Khurram Javed: Why AI Models Stop Learning, and How to Start It Again

节目发布 2026-08-18 · Sequoia Capital
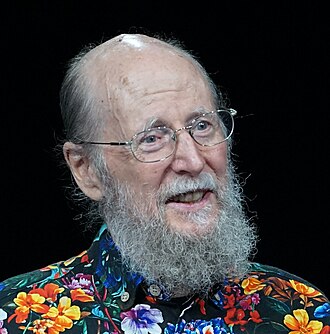
理查德·萨顿 库拉姆·贾维德 主主持人
EDITED TRANSCRIPT · 依据现场录音编译整理,可划线生成便签
编者按:本文整理自红杉资本与 Oak Lab 两位联合创始人的一场对谈。理查德·萨顿(Rich Sutton)是强化学习的奠基人、《苦涩的教训》(The Bitter Lesson)的作者;库拉姆·贾维德(Khurram Javed)是持续学习研究者,萨顿在阿尔伯塔大学指导的学生,如今与他共同创办 Oak Lab。对谈从《苦涩的教训》谈起,涉及大语言模型的局限、合成数据之争、大世界假设、持续深度学习的算法路径,以及 Oak Lab 的研究纲领。全文依据现场录音编译整理,仅删去口语枝节与寒暄。

不是我怪,是这个领域怪

萨顿: 人们有时候觉得我的观点很激进。他们提问的开场白常常是:你的想法跟所有人都不一样。但我完全不这么看。我觉得我是在用平常的方式思考,反倒是其他人想得有点怪。

我是认真的。是最近这些年人们才想得怪了。在 AI 热潮之前,你根本不必说「持续学习」(continual learning),因为不持续的学习根本说不通。一切学习都是持续的。我们始终在行动,始终在学习,这才是正常的思路。我不怪,怪的是这个领域,是这个领域非要管它叫「持续学习」。它就是学习。

一个濒死之人的选择

主持人: 今天我们非常荣幸请到了理查德·萨顿。理查德,你创立了强化学习,写了这个领域的奠基教材,培养了戴维·席尔瓦(David Silver)这样的关键人物,还写下了《苦涩的教训》,我认为那是这个领域的圣经。感谢你抽出时间。与你同来的是库拉姆·贾维德,你的联合创始人,也是你在阿尔伯塔大学的学生。两位一起创办了 Oak Lab,我很期待谈谈这家公司。今天我们先从《苦涩的教训》说起,谈谈当下的局面,谈谈大语言模型能不能把我们带到目的地,然后再转向你们的研究纲领和 Oak 的计划。

理查德,我本来想从《苦涩的教训》开始,但其实想先往前回溯。几十年前,你决定把职业生涯押在强化学习上,把阿尔伯塔大学建成了这个方向的重镇,而那时这个领域还在襁褓之中。是什么给了你这份笃定?

萨顿: 不然还能干什么呢?我们想弄清楚心智是怎么回事,而学习是心智的核心部分,拥有目标也是心智的核心部分,是智能的核心部分。所以我只是在一直以来的想法上加倍下注而已。

主持人: 当时人们觉得你疯了吗?

萨顿: 那时候是 AI 寒冬。

主持人: 哪一年?

萨顿: 2003 年。说实话那段经历有点荒诞。2003 年我病得很重,其实是在等死,癌症。但我没死成,你知道,我努力了好几年,一次缓解之后又没死。于是我想,好吧,既然死不成,拖了这么久,不如干脆再找份工作。所以我去了阿尔伯塔,开始在那里教书。

最后我没有死。现在拿这件事开玩笑,但当时是非常严肃的。而更要紧的问题是:只剩几个月可活的时候,我为什么还继续做研究?我总会想起据说是本杰明·富兰克林说过的一句话:如果你想知道一个人为什么做某件事,答案几乎总是两者之一,要么是习惯,要么是虚荣。我觉得这话大概是对的。也许是我习惯了一直做的事,也许是虚荣。我想更可能是习惯,因为我当时快死了。

主持人: 天意。

萨顿: 对我来说,保持坚定一向不难。这个回答我还想再说长一点。

主持人: 请讲。

萨顿: 人们有时候觉得我的观点很激进,提问时总说我的想法跟别人多么不同。但我完全不这么看。我觉得我是在用平常的方式思考,是其他人想得有点怪。

我是认真的。只是最近这些年人们才想得怪了。你去看看人们过去怎么理解心智,哪怕只往回看十年,你会发现那些想法都是:学习很重要,你得有目标,感知很重要。我们是低层次的存在,以极快的速度产生动作、接收数据,同时又必须在更高的层次上思考。再往前,在这场 AI 狂热之前,你根本不必说「持续学习」,因为不持续的学习根本说不通。一切学习都是持续的。学习不是一个特殊阶段,我们始终在行动,始终在学习,这才是正常的思路。我不怪,怪的是这个领域,非要管它叫「持续学习」。它就是学习。

主持人: 「不是我怪,是别人都怪。」这是句不错的座右铭。整个领域都庆幸你活了下来,感谢你一直在推动 AI 的前沿,也感谢你培养了那么多同样在推动前沿的学生。过去二三十年,你是怎么挑学生的?

萨顿: 你这是给我一个谦虚的机会。我喜欢谦虚,喜欢指出那些伟大的决定其实都是碰巧发生的。对学生,我就是这种感觉。我不觉得自己挑学生挑得好,有时候运气好,有时候运气差。我看着库拉姆,心想,有时候你就是碰上了真正出色的人。戴维·席尔瓦是他挑的我,不是我挑的他。库拉姆,我是怎么得到你的?

贾维德: 我的硕士不是跟你读的,当时打算去业界。后来我们在一个项目上合作起来,也是自然而然的。我做过一个东西,理查德在一次会议上听人提到我做过,我就被拉了进去。合作非常顺利,我很开心,理查德也觉得很好。六个月之后我们有了些进展,把它写成博士论文选题就成了顺理成章的事。所以我从没申请过,也从没问过你愿不愿意当我的导师。我们先一起干活,然后觉得这可以是一篇不错的论文,之后我才去申请博士。

主持人: 人生的路总是出人意料。

《苦涩的教训》二十六个字

主持人: 把我们带回 2019 年。你写了《苦涩的教训》,后来它成了这个领域的经典。2019 年写这篇文章其实时机很微妙:ImageNet 是 2009 年,AlphaGo 是 2015 年。是什么促使你在 2019 年回顾并写下它?那时大语言模型的规模化范式还没起飞,但深度学习已经证明了自己。

萨顿: 那篇文章酝酿了很久。正如文中所说,这是一件你可以观察几十年的事。它至少同样多地来自符号 AI 那一轮,我亲身经历过。核心就是不要被「把人类知识塞进去」的诱惑分心,而要专注于问题本身需要什么,以及如何随算力扩展。至少一年前我就写过它的不同版本,也做过演讲。它不是对某个时刻的回应,而是对我漫长经历的回应:不同的人用不同的方式思考怎样造出聪明的系统。

主持人: 《苦涩的教训》的精髓是什么?我在会议上最常听到的一个词就是「吃了苦涩教训的药」(bitter lesson pilled)。以这个词的流行程度,想必已经被以各种你未曾预料的方式曲解和滥用了。你认为它的精髓是什么,人们在理解它时又错在哪里?

萨顿: 你让我想起我最近在 X 上发的一篇帖子,我试着用二十六个字概括苦涩的教训。大意是:不要被人类知识分心,AI 历史上已经分心过很多次;要专注于能随算力扩展的方法,比如搜索,比如学习。所以它的核心是算法和改进。它不是说你不需要精巧的算法,你需要,但你要的是能随算力扩展的精巧算法。

主持人: 而不是随数据扩展。

萨顿: 而不是随人类的输入扩展。接下来的问题我可以预料,那大语言模型呢?

主持人: 对。它们与你的论断相符还是相悖?

萨顿: 我想过这个问题,也发过一篇帖子。结论是:大语言模型既是苦涩教训的正面例子,也是反面例子。首先,大语言模型实现了随算力的巨大扩展,你可以把整个互联网吸进去,规模扩得极大。这是靠可扩展的方法得到远为强大的系统。但再往后,它终究会被那些信息所限。互联网是有限的,很难再获得更多例子。而世界很大,比互联网上存的一切大得多得多。所以到最后,它成了一个例证:我们过度依赖人类知识,最终被它拖住。

合成数据是个大错误

主持人: 我想追问一下。眼下基础模型实验室的大量工作是合成数据生成,为的是跨过「现有人类互联网」这块化石燃料。作为大语言模型规模化范式的一部分,合成数据生成算不算一种利用算力的通用方法?

萨顿: 不算。那就是个大错误。

主持人: 为什么?

萨顿: 这也许是下一个大教训。这个想法在阿尔伯塔已经流传了五到十年,我们称之为「大世界视角」或者「大世界假设」(big world hypothesis)。库拉姆后来把它写成了一篇小论文,就叫《大世界假设》。

贾维德: 大世界假设是说,世界无限大,有无限多的东西要学。你可以让人去生成合成数据集,但总会有更多东西要学。正因如此,如果能直接从经验中学习,把人从循环里拿掉,你就能有无所不能的系统。因为世界很大,我们想让它们做的任务太多了,它们能从自己的经验中学会做任何事。

回到合成数据的问题:谁来决定什么是好的合成数据、什么是坏的?我可以写一个程序输出海量合成数据,而那些数据会损害模型。眼下的答案是人来决定。这就是瓶颈:你可以让人来决定如何生成这些数据集,但这条路要扩展,就需要知道哪种数据集好、哪种坏的人类专家。所以它被人卡住了。

主持人: 难道不是我的损失曲线来决定吗?用这个数据集比那个数据集进步了多少,曲线不就说明了?

贾维德: 对。但如果 OpenAI、Anthropic 和所有新兴大实验室的工程师都去度假了,谁来生成合成数据?问题就在这里。它不来自智能体的经验,不是智能体自己生成的,必须有某个人来决定该生成什么样的合成数据,而这需要人类专长。举个例子,假如你想让系统做一件物理上很有挑战的事,比如一架像蝙蝠一样靠回声定位飞行的无人机。什么样的合成数据是对的?我想你得雇领域专家去弄清楚该要什么数据,把它生成出来,然后也许能从中学到。但领域专家得先存在。到那一步,我们就被人类专长卡住了。

主持人: 但你可以有无限多的合成世界,而现实世界是有限的。

贾维德: 还是回到回声定位的例子。我要的就是这个:一架能用回声定位自身、自主移动的无人机,这是我的目标。这个机器人本身就在生成自己的经验,它完全可以从自己的经验中学习。可不管你生成多少合成数据,哪怕你的合成数据涵盖了五十个不同的宇宙,不先由人把这件事弄明白,它就完成不了这个任务。

萨顿: 我首先要说,合成数据是错的。它不会是对的,它是一个合成的世界,不是真实世界,而这一点很要紧。世界极其复杂。你写一个小程序(生成合成数据的必然是个小程序),它造出来的只会是一个小世界。

比如,对我来说重要的是你此刻脑子里在想什么。你会说,那我为什么不弄些合成数据来告诉我别人脑子里在想什么?不行,别人的心智不可能有合成数据。而别人的心智对我们很重要。比如我今天在跟你们谈投资,我在乎你们心里在想什么,这种东西怎么可能有合成数据?说真的,任何东西你都弄不到合成数据。无人机在物理世界里如何与环境交互,摩擦力,电机里的磨损,这些你都弄不到合成数据。世界无限复杂,任何对它的模拟都微不足道。

大世界假设,说白了就是:世界比你的心智、比任何智能体都复杂得多得多。这是显而易见的,因为世界里包含着许多其他智能体。既然世界如此复杂,你就不可能做到任何号称最优或完美的事。你必然是不完美的,你必须用近似,而且那些近似会很粗糙。正因如此,如果非要给持续学习找一个理由,这就是根本理由:我们会遇到这个广袤世界的某个特定角落,必须学出一个针对所在角落调校过的近似,而不是针对我们不在的其他所有角落。

主持人: 我再追问一次。抱歉我是为了争论而争论,但我想弄明白。据我了解,最新一批自动驾驶公司里,很多主要是在仿真环境里训练的,然后做一些后训练来确保它们在真实世界里能用。这条流水线一直非常有效。

贾维德: 这里该问的重要问题是:造那个仿真器用了多少工程师?我们是否准备好宣布,只有那些能雇一大队工程师先做出仿真的问题才值得解决?我敢肯定他们迭代了很多轮:做仿真,在里面学,发现仿真到现实的差距(sim-to-real gap)不可接受,再修。人一直在循环里修仿真器。他们从真实世界拿到反馈,人再去修仿真器。为什么不能把人拿掉,让智能体自己来?

萨顿: 而且它真正上路的时候,还是会有意料之外的事发生。

贾维德: 那正是你真正需要从经验中学习的时候。

主持人: 所以你们的意思是,来自经验的数据,远远多于人类策划、制造的数据所能达到的量。

贾维德: 对。而且从仿真中学习显然有价值,也有正确的做法:智能体从自己的经验中学出一个模型。智能体自己学出来的模型好得多,因为模型不对时它能靠持续学习去修正。如果仿真器是人造的,那只有人发现哪里不对,模型才会更新。所以,规划很重要,智能体应该从仿真器中学,但那得是它们自己造的仿真器。

先验与学习不该为敌

主持人: 我想转到《苦涩的教训》的另一部分:去掉人类知识。你在文中写道:为了在短期内取得可见的进步,研究者总想利用自己对领域的人类知识,但长远看唯一要紧的是对算力的利用。你的学生戴维做的 AlphaGo 和 AlphaZero,在我看来就是去掉人类先验的一次胜利。那个结果让你意外吗?

萨顿: 当然让我很高兴,让我觉得自己得到了证明。但结果本可能是另一个方向,因为先验知识确实能帮上忙,先验知识没有什么错。我在《苦涩的教训》的开头就说了,先验知识和学到的知识之间没有理由非得冲突。你可以先放一些先验进去,然后开始学。原则上这两者没理由对立,它们都是关于知识的。生活就是获取知识、拥有知识。天性与教养怎么就成了敌人?先验就是你已经有的,然后你学到更多,它们本该是朋友。但正如我在文章开头说的,实践中它们一直是敌人。实践中,那些偏爱现有人类知识的人总想让它赢,于是想贬低或者忽视学习。

所以现在你们大概觉得我是一个热爱学习、想抛弃先验知识的人。可我其实是一个对心智感兴趣的人。心智就是:你有先验知识,然后得到更多,得到之后它又成了你的先验,如此不断累积。这两样东西是一起运作的。我之所以显得像个只关心学习的人,是因为全世界其他人都在说:只要知识够多就行,不需要学习。大语言模型就是把所有知识塞进系统,然后运行的时候不再学习。它在跟人说话,在交互,可权重绝对一动不动。所以怪的不是我,是你们这些人,你们竟然相信一个不再学习的东西能拿出博士级别的经验和专长。怪的不是我。

主持人: 所以你的建议是,让算法跑得久得多,再把先验数据一点点滴进去?

萨顿: 持续学习。两者都重要,但长远看,你必须获取新知识,并且把获取新知识这件事组织好,长远看唯有这个要紧。在这个过程中,当然会有一些是你之前就有的。

想想将来有了智能机器人会怎样。我们会让它们全部从零开始学吗?还是复制它们,让它们从各自所在的地方接着学?它们是数字的,复制很容易。所以与其花天文数字的钱从互联网上把它们重新训练一遍,我们只会复制这个智能体,从那里接着学。从这个意义上说,先验知识其实可以不用管了,因为你直接从上一个机器人那里复制过来就行。

权重从不改变

主持人: 请描述一下,你心目中一台从经验中学习的机器或计算机是什么样子?

萨顿: 它可以是一个机器人,也可以完全活在互联网上。比如在互联网上给数据包选路,做法对经验敏感,越做越好。或者通过用户界面与人交互,在你的手机或电脑上,随时间变得越来越好。一个智能助手必须随时间变好,它必须知道你想要什么。

主持人: 你是否认为,当下流行的基于大语言模型的助手,不算经验学习者或持续学习者?如果是,根本的差距在哪里?

萨顿: 你是认真的吗?

主持人: 它们会记住关于我的事,会做一些上下文学习(in-context learning)。

萨顿: 它们的权重从不改变。

主持人: 顺便问一句,只改一小部分权重够不够,还是所有权重都得变?

萨顿: 想想创造大语言模型的过程中,那些结构的建立、新概念的生成,全都是权重学习。你希望能继续做这件事,而不是只做一次。

主持人: 换个说法:我们在发布模型之前做了太多预训练和后训练,之后它们就不学了?

贾维德: 唯一的分歧点就是,之后我们不让它们学了。预训练多少都行,后训练也没问题,但当我在使用模型的时候,它就停止学习了。你可以给它更多上下文,通过上下文改变模型的状态。它已经学会了:如果状态不同,如果状态里有新东西,就用它来做下一步预测。但模型本身没有在学习。

主持人: Cursor 的 Tab 补全模型确实会根据使用情况更新。

贾维德: 那些模型的权重是在变的。Cursor 的 Tab,我想还有它的 Composer,也在更新。这是两个持续学习的例子。但可以做得好得多。据我了解,他们的做法是:大量的人在用 Tab,他们收集来自数百万或数千用户的数据,然后用这批数据对策略做一次更新。这可以奏效。但假如我想教这个模型一件很具体的事,我不想跟十万个别人争论各自想教模型什么,我想教我的模型一件非常具体的事,教给我这一版模型。我不在乎模型里来自其他人的共享知识。所以那是一种非常低效的做法。

主持人: 目前的做法似乎是:所有人共通的基本技能学在权重里,个性化则以上下文的形式发生。这不是学习应有的正确模型吗?还是说所有上下文都应该活在权重里?

贾维德: 上下文也可以在状态里,两者都可以。但你仍然需要能更新权重。举个例子,一些很好的案例来自人类残障研究。当一个人经历了改变其心智或某种感官的事,你能看到他们适应。比如我们有本体感觉,有内部传感器告诉我们身体的姿态,走路要靠它。有些人完全丧失了这种能力,于是根本无法行走,因为那正是他们行走策略的根基,深深刻在大脑里。但经过两三年,他们能靠看着自己的脚重新学会走路,用视觉反馈来替代。所以大脑的可塑性惊人:一件二十年来一直成立的事,当它不再成立时,大脑能更新它、抛弃它。我认为这正是我们希望系统拥有的、极为有用的能力。

动物不靠监督学习

主持人: 人类婴儿和动物的学习方式能给我们什么启发?你们从中汲取多少灵感?

萨顿: 我们汲取了很多灵感。我们不把「AI 必须像自然系统那样行事」当作要求,婴儿也好,人也好,动物也好,只是灵感来源。从动物学习中取灵感,但不受其约束。

主持人: 这与苦涩的教训一致?

萨顿: 对。

主持人: 生物学习中有什么东西,是今天的系统里没有、而我们最应该借鉴的?

萨顿: 我觉得我现在只是在发表意见,不过都是显而易见的意见。我认为很明显,没有任何动物是靠监督学习来学习的。因为没人给我们示例,告诉我们肌肉该怎么抽动,而肌肉抽动才是我们的输出。

主持人: 但整个学校教育都是监督学习。

萨顿: 绝对不是。就算是,学校也只占我们所学的极小一部分。我们学会看,学会走,学会世界如何运作。而且即便在学校,也没人告诉我们肌肉该怎么抽动。

主持人: 我掌握的知识和技能是在学校靠监督学习获得的。

萨顿: 我不是说向他人学习、他人的传授不重要,那极其重要,语言也极其重要。但我们缺的是什么?没有监督学习,没人给我们目标值。你听到正确答案:法国的首都是哪里?我们知道答案是巴黎。但没人告诉我该怎么发「巴黎」这个音。你说答案是巴黎,我听到你的话,然后我用另一套肌肉运动来产生「巴黎」这个答案。这不是字面意义上的监督学习。

所以我认为这确实成立。首先,学校无关紧要。松鼠不上学。动物不是那样学的。学校是一个非常特殊的东西,连我们人类在几百年前都没有。它不属于智能的本质。把学校这个我们作为动物本来不做的事当成学习的首要范例,是一种误导。

主持人: 真希望我父母当年能听你说这番话,省得我被送去上学、受那些规矩。

主持人: 问题是,松鼠很擅长从树上跳下来,但松鼠不会证明数学定理。我想学证明数学定理,就得去上学。

萨顿: 它们也没有 DVD 和 iPod。有很多事它们能做我们不能。至于数学定理,它们也不下棋。这有点像莫拉维克悖论(Moravec's paradox):那些我们视为高度智能的高级事务,对计算机来说反而容易;而那些平常的事,比如运动、带注意力的视觉,反而很难。我认为监督学习是好东西。我只是喜欢找显而易见的事:没人能靠给示例来教我们抽动肌肉,因为根本不可能。我们必须自己去抽动肌肉,自己去弄明白。

贾维德: 而且他们给的答案也会是错的。如果我把嘴、舌头和声带按理查德发「巴黎」的方式一模一样地动一遍,肯定会发出一个截然不同的声音。所以从某种意义上说,理查德也好,任何人也好,都不知道用我的身体发出那个音的正确方式,只有我自己知道。

主持人: 在我看来,那些最原始的感觉运动能力,尤其是物理世界中的运动,我同意本质上是从经验中学的。但更高层次的抽象,那些更接近「人类何以伟大」的东西,多数并不在这种低层次的感觉运动学习里。你们的世界模型是否从感觉运动学习一路涵盖到高层?

萨顿: 对,这正是我们的抱负。顺便说一句,松鼠也能做一些相当抽象的事。

主持人: 松鼠能做的最酷的事是什么?

萨顿: 它总能钻进你的喂鸟器,不管你设了什么障碍,它都能找到新的跳法和爬法。

贾维德: 它们算轨迹算得很准。动物对物理世界的理解很到位,并不需要我们想象中发射自己上太空时那种心算。

萨顿: 摔倒时护住自己,它们能实时用正确的方式做到,避免受伤。

主持人: 好吧,有道理。

萨顿: 我认为这只是程度之别。我倾向于认为其他动物与人类非常接近。一味强调我们与动物有何不同,是一种傲慢。看到共性更好。我们只是程度上的差异,当然,社会和文化给了我们巨大优势,语言也给了我们巨大优势。

想象、抽象与范式转移

主持人: 我想再追问一下,因为我想替索尼娅(Sonya)撑一下腰。我相信动物和儿童从经验中学习,并靠经验做出了了不起的事。我儿子两三四岁的时候,我常感叹:真有意思,没人教他,他就能学会这些。但同时,索尼娅的意思是,人之所以为人,能上太空,能造火箭,这些并非百分之百从经验中学来的。发射火箭之前,你得先在脑子里抽象地把它想通,而这不是从所谓的「经验」中学来的,因为你不知道它能不能成,你得靠想象。我们怎么教机器去想象此前不存在的东西?这大概是我们想追问的,因为这一点我们还没弄明白。

萨顿: 这点我其实同意你。你得能规划,得能想象。

贾维德: 你觉得一千年前的人类,在做出我们谈的这些事之前,是否同样智能?假如那个时代的人接触到今天的文化,能不能获得同样的技能,开始做有用的事?

主持人: 即便在过去一万年里,我认为人脑也没有多少演化。

贾维德: 根本上是同一台机器。

主持人: 根本上是同一台机器,但我们积累了一万年的知识。而我通过上学、通过监督学习获得这一万年的知识,比靠经验去学快得多得多。

贾维德: 对,你说得完全对。我们希望系统从经验中学,而它们经验的一部分就是接触我们的文化,学习我们的文化。它们应该从中学,这都很好。但我们来谈谈有人做出范式转移式的事情时是怎么回事。大家都举爱因斯坦的例子,但我认为例子很多,学习本身也是一个例子:从「编程」到「学习」的视角转换。范式转移发生的时候,我会说,是一个积累了所有这些知识的人,从自己的经验中构建新的抽象,用这些抽象来规划,进而发现新知识。这种提出新抽象、学出模型、用模型规划的技能,在我们当下的系统里完全缺席。你可以在人类知识的边缘看到这个问题,但也可以在感觉运动流的层面研究它。

萨顿: 所以我们并不是在原则上争论,我们需要形成抽象,才能在高层次上推理。你们刚才快要做我说过永远不该做的事了:争论先验知识重要还是获取知识重要。你们刚才说的就是这个。你说,你还是得学东西;你又说,我可以从文化、从先验知识中获得。但这两者不该相互为敌。

主持人: 具体说到范式转移,我们怎样造出一台知道何时该转换范式的机器?

贾维德: 我想是通过它的经验。它必须通过自己的经验。它不能依赖人类知识,因为我们的前提就是人类只看到一种范式,而我们想要另一种看世界的方式。所以它必须通过自己的经验找到更好的东西,也许泛化更好、预测更准,也许在别的方面更好,但必须来自它自己的经验。

萨顿: 我们这个领域尚未见到的重大能力,是学出一个模型,然后用这个模型来规划。数学的事我们能做,AlphaGo 我们能做,因为在游戏里模型是已知的,我们知道走法怎么运作;在数学里我们知道算子是什么,知道 Lean 会把我们从一个知识状态带到证明的下一个状态。但如果模型必须学出来,我要直说了,这也许是个奇怪的例子,但我看不到这个领域里有任何「学出模型、再用模型规划」的实例。

贾维德: 至少没有用自主发现的抽象来做的。有人说,我就学一个预测下一秒或下一毫秒会发生什么的模型。但我们的心智模型不是这样运作的,我们的模型更抽象,性质相当不同。

阿尔伯塔计划

主持人: 我喜欢你们的一点是,你们不是坐着空谈,或者哀叹世道,你们很讲行动,所以才创办了公司。我们来谈谈这个。理查德,2022 年你提出了一个非常具体的十二步计划,即「阿尔伯塔 AI 研究计划」(Alberta Plan)。讲讲它吧。

萨顿: 阿尔伯塔计划的由来是,我们有一些总体想法,但也需要把它们拆成更小的块。十二个步骤就是把特定的块具体化的尝试。早期有一个非常重要的步骤,第二步,持续深度学习(continual deep learning)。我们认为它几乎是最重要的一步,因为它解锁了其他一切。如果你能做持续深度学习,你就能持续更新自己的世界模型。然后,如果你知道怎样把抽象做对,步骤的后半部分全是关于如何把抽象做对的。我说「做对」,不是指找到「正确的抽象」,因为没人能说什么是正确的抽象,那取决于你所在的世界。你的智能体必须为它所在的任何世界学出正确的抽象。所以也许关键就是这两件事:你必须找到正确的抽象,你必须能做持续深度学习。

贾维德: 我想这个领域很多人都意识到我们需要模型、需要用模型规划。但抽象告诉我们模型应该以什么为条件:模型该预测什么?你要做什么,然后会发生什么?更重要的是,这些抽象从哪里来?我很喜欢顶尖运动员的例子。你问顶尖运动员他们怎么做某些动作,他们会有一些古怪的小众术语来描述非常具体的事情,「我做这个」,然后有个名字。如果他们只是自己练,有时候甚至连名字都没有。那他们是怎么想出这些抽象的?这在某种意义上正是缺失的关键,阿尔伯塔计划的后半部分回答的就是这个。

灾难性遗忘可以治愈

主持人: 能谈谈持续深度学习这部分吗?今天存在的是一个算法上的差距,还是仅仅是部署、基础设施、数据隐私上的实际差距?如果我想基于用户交互天真地更新权重,今天就能做到,对吧?在你们看来,走向持续深度学习,我们最缺的是什么?

贾维德: 绝对是算法差距。你可以做那个天真的办法,但你会看到各种各样的问题。比如你说,我拿一个样本,然后用它更新整个模型。你会碰到这个问题:模型里之前的所有知识都受到了负面影响。而目前绕过它的办法恰恰是 Cursor 的做法:他们不用一个样本,而是用来自大量用户的一大批数据。在能拿到这种数据的场景里,你可以做持续学习。但大多数场景没有,大多数场景你只有一条数据流。这时候用天真的办法,就会以极具破坏性的方式彻底摧毁你的先验知识。

主持人: 灾难性遗忘(catastrophic forgetting)。

贾维德: 对。

萨顿: 但它完全可以治愈。你得有正确的算法。

主持人: 药方是什么?

萨顿: 首先要做我们所说的步长优化(step-size optimization)。意思是网络里每个权重都得有各自的步长,有的动得快,有的动得慢,而且你得对每个权重的步长做元学习。网络里大部分权重的步长会很小,这样你用新样本训练时它们就不会被破坏,变化只发生在恰当的地方。

其次,你得用某种形式的「生成与检验」(generate and test),在特征空间里做。也就是说,你提出新的特征、新的单元,而不是靠沿梯度走。因为梯度是一个非常慢的过程:只有当你知道某个方向有用时才朝它移动,这永远很慢,也不能给你一条通往越来越复杂、持续学习的路。你需要一种东西,能直接提出一批新单元,然后从那里往下走。

我可以说一个具体的东西,让这件事落地:我们有一个叫「持续反向传播」(continual backprop)的算法,几年前发在《自然》上。它和反向传播完全一样,只是你还会不断种下新的种子,即用随机权重新初始化的单元。反向传播只在时间开端有随机权重,随着训练进行,随机性带来的所有多样性都被用光了。而持续反向传播不断注入一点随机性,一点生成与检验:生成,然后由反向传播的运算来充当检验者。你需要这个。如果把这些东西真正结合好,我认为你会得到新一代远为强大的持续深度学习。这就是我们希望在未来几年做成的事。

主持人: 很好。你们认为这些算法能用在当下的局面里吗?人们正在扩展大语言模型,试图让它们持续学习而不发生灾难性遗忘。

贾维德: 当然。不过我不认为你能拿一个现有模型说「我就用这些算法开始更新它」,因为这些算法是在元学习「如何学习」。所以实际上你得说:我要从零开始学。比方说,我要训练一个新的基础模型,但用这些新算法来训练。这些新算法在学知识的同时,也在学如何学习未来的东西,两件事同时进行。然后我认为你就能学新东西而不发生灾难性遗忘。

一颗自洽的心智

主持人: 相对于当下的局面,你们公司要做的最激进的事是什么?

萨顿: 又回到「我不疯,是别人都疯了」。

贾维德: 也许没那么激进。2016 到 2018 年间,很多人都在深入探索这些想法。只是他们的设定要局限得多:他们会说,我们有一个问题分布,在这个特定情形下这么做。而我们想从单一的经验流出发去做,所以我们的方法应该更普遍适用。很多人探索过这个,但没人在通用设定下探索过,让得到的算法处处适用。

主持人: 那么,你们的新公司要做的、别人没在做的最激进的事是什么?

萨顿: 最有雄心的事吧。记住,我不觉得自己怪,所以我不想说「激进」。最有雄心的,我想是试图拥有完整光谱的知识,既关于极小的事,也关于极大的事。比如思考怎么乘飞机从一个城市到另一个城市,那是件很大的事,就像你的太空飞行的例子,只是更贴近常识,因为我们很多人都坐飞机,而我们所有人都在生活的方方面面使用抽象。连松鼠都用抽象。所以,拥有从小到大的整个知识光谱,用统一的方式处理它,并且让它能自我维护。

那个大问题永远是:你有一个知识系统,是什么让其中的知识保持正确?大语言模型里知识的正确性靠什么维持?靠人做了大量后训练,确保它是对的,然后把它冻结。这就是它保持正确的方式。可我们的心智一直在变动,却有某种东西让它保持有序、连贯,最终安顿在一个好的地方,而不是漂进疯狂之地。我认为这是我们最大的雄心:一颗自洽的心智,能不断训练自己,并让自己保持连贯。

主持人: 这个愿景如此宏大,把所有这些东西统一到一颗心智里的想法如此有雄心。

萨顿: 我认为它触手可及。现在是 2026 年,我们的计算机这么快。它是不是雄心大到够不着?还是说我们对每一步该怎么做已经有了眉目?我认为我们有愿景,也有眉目。我不认为这不合适。

两千瓦与二十瓦

主持人: 你们的愿景里有一个二十瓦的万亿参数模型,这听起来相当有雄心。

贾维德: 确实有雄心。从某种意义上说,以现有技术这也不可能,光是把一万亿参数存在内存里,以现有的内存技术恐怕就不止二十瓦。但我们真正考虑的是,情况在变好,算力在变便宜、变得更节能,那五到十年后我们会在哪里?我认为五到十年,加上正确的算法,我们完全可以到达一个让这件事成为可能的世界。

主持人: 五到十年是摩尔定律的两个数量级,这是标准的改进速度。如果每十八个月翻一番,十年给你两个数量级。所以要让库兹韦尔(Kurzweil)式的说法成立,今天你应该能用两个数量级之上的功率做到,也就是两千瓦?

萨顿: 两千瓦。如果今天能用两千瓦做到,那十年后就能用二十瓦做到。

主持人: 你们觉得能用两千瓦做到?研究实验室里有很多人手里的算力远不止这些。

萨顿: 我认为有了正确的算法,现在就能比这更高效。

主持人: 如果能更高效,为什么没有人做到?人们又不是就想把钱都烧掉。

萨顿: 有时候看起来他们就是想。我想那是他们证明自己是真汉子的方式,消耗大量能源。

贾维德: 至少我看各个研究团队,没见到有谁相信这是可能的。如果你不相信,你就不会去啃那些技术难题。

主持人: 是它不可能,还是系统里浪费太多?是不是有人知道怎么高效地做,而同一个实验室里有十倍的人在干别的,十个人里九个在浪费?

贾维德: 我的理解是,我们困在了一个局部极小值里。如果想转向这些新型算法,几乎不可能不先变差再变好。开始探索这些新方向时,你第一天不会得到最先进的性能,因为这是一个不同的范式。但那条路通向相似的性能,在更高的能效上。而那些大实验室被产品锁得太死,不可能走一条先变差的路。

主持人: 因为他们现有的范式还能继续扩展,而新范式需要下注。

贾维德: 而且他们得解决一些困难的技术问题,那些问题我们已经想了很多年。我们认识一些同样想了很多年的人,跟他们聊过之后,我觉得这是可行的,但你需要在这些难题上长时间地思考。

语言只是智能的四分之一

主持人: 如果 Oak 一切顺利,公司会怎样?你们在建一家什么样的公司?

萨顿: 如果一切顺利,我们实现这个架构,拥有真正的持续学习,能形成抽象,从而做规划和推理,拥有某种真正的智能。到那时会发生什么,很难准确想象。

主持人: 人类会变得无关紧要。

萨顿: 我完全不这么认为。

贾维德: 我们也不这么认为。

萨顿: 我认为世界会变得更精彩、更有意思,对人类而言尤其如此。但有一类东西你得替它担心:大语言模型。这件事最终发生时,它们可能有风险。当然它们会有一段好日子,已经有过了,非常成功。为了清楚起见,我要说:大语言模型是一项惊人的科学突破,是神经网络娴熟运用语言的突破,完全出人意料。语言曾经一直是符号方法的堡垒,而它们彻底改变了人们对此的看法。这是个大突破。

让我沮丧的是,我们本该庆祝在 AI 问题的一个子集上取得了如此大的进展,好好享受它。可它偏要假装自己是 AI 的全部。智能不全是流畅、娴熟地运用语言,还有多得多的东西。语言是重要的一部分,大概占智能的百分之二十或四分之一。还有更多。我们还没完。

主持人: 如果一切顺利,你们设想的是一颗单一的心智,从学会在树枝间荡秋千到造飞船,把今天谈的所有事都做了吗?是一颗心智、一套权重来做这一切吗?

萨顿: 是一个单一的设计。会有许多不同的心智。

主持人: 也就是说,一个设计,对不同的环境做出反应。

贾维德: 而这个心智的不同版本会学到不同的东西,因为它们的经验不同。这又回到大世界假设:有无限多的东西要学,一个系统学不了无限多的东西。理查德已经提过,如果你有两个这样的系统,是世界上最大的两个系统,那么它们显然无法给彼此建模,因为它们同样复杂。所以单一系统永远到不了能学会一切的地步。永远是多个系统,各自从自己的经验中学习。

从小团队开始

主持人: 两位在招人吗?在找什么样的人?

贾维德: 在招。初始团队大部分人选我们心里已经有数了,都是长期思考过这些想法的人。我们会采取稍微不同的做法,因为这是一个不同的范式,很快变大没有意义,因为每一个我们雇的人都得看到我们所看到的,而不是每个人都能看到。所以我们会从小开始,慢慢扩到一二十人,再往下走。

萨顿: 我们希望高度一致。

贾维德: 我们希望高度一致,这样才能高效协作,把进展扩大。

主持人: 非常好。我很喜欢这场对话,感谢你们抽时间分享正在做的事。你对强化学习和算法设计的未来有着罕见的深刻思考,今天能与你一起探讨,是真正的荣幸。谢谢。

萨顿: 非常感谢,这是我们的荣幸。
本期讲者
理查德·萨顿强化学习奠基人,与 Andrew Barto 合著经典教科书并共获 2024 年图灵奖;2003 年起任教阿尔伯塔大学,2019 年发表《苦涩的教训》,2025 年与 Khurram Javed 创办 Oak Lab。
库拉姆·贾维德Sutton 在阿尔伯塔大学的博士生,Oak Lab 联合创始人;提出「大世界假说」论文,研究方向为持续学习与元学习。
主持人两位投资人主持人,负责追问《苦涩的教训》、合成数据、LLM 是否在学习等争议点。
章节 · 点击跳转视频
0:00 「持续学习」本来就是学习 ▶ 正在看
0:59 寒冬中投身强化学习的缘由 ▶ 正在看
7:10 《苦涩的教训》的精髓与误读 ▶ 正在看
10:59 合成数据之争与大世界假说 ▶ 正在看
17:49 先验知识与学习本不该为敌 ▶ 正在看
22:02 权重不变的 LLM 算学习吗 ▶ 正在看
26:09 动物不靠监督学习,学校无关本质 ▶ 正在看
31:48 造火箭需要的想象从哪来 ▶ 正在看
36:54 阿尔伯塔计划与灾难性遗忘的解药 ▶ 正在看
43:43 20 瓦万亿参数与行业的局部极小值 ▶ 正在看
49:03 Oak Lab 的愿景与小团队策略 ▶ 正在看
本期论点
本期回应
9:29
《苦涩的教训》否定的不是精巧算法,而是无法随算力扩展的算法 靠学习智能主要靠什么长出来?理查德·萨顿
23:21
创造新概念的权重学习不该只发生在预训练一次,而应在模型使用过程中持续进行 靠学习智能主要靠什么长出来?理查德·萨顿
26:52
没有任何动物是靠监督学习来学习的,没人给得出肌肉该如何抽动的样例 靠学习智能主要靠什么长出来?理查德·萨顿
37:26
持续深度学习是通往通用人工智能最关键的一步,它能解锁其余所有能力 靠学习智能主要靠什么长出来?理查德·萨顿
37:50
不存在客观上正确的抽象,智能体必须自己在所处世界里学到什么抽象才算对 靠学习智能主要靠什么长出来?理查德·萨顿
51:55
单个系统永远不可能学会一切,智能必然是多个系统各自从自身经验中学习 各管一摊智能能装进一个通用系统吗?库拉姆·贾维德
10:26
世界远大于人类写在互联网上的一切,大语言模型终会被互联网信息的有限性卡住 会卡住光靠现有的数据,能学到真实的世界吗?理查德·萨顿
15:30
世界远比任何智能体的心智复杂,智能体只能依靠粗糙的近似,因而必须持续学习 会卡住光靠现有的数据,能学到真实的世界吗?理查德·萨顿
32:34
发射火箭这类事情不可能完全从经验中学来,必须先以抽象方式把它想清楚 需先想清光靠现有的数据,能学到真实的世界吗?主持人
其他论点
0:28
所有学习本来就是持续的,「不持续的学习」这个说法本身说不通 理查德·萨顿
39:18
持续学习至今未实现是算法层面的缺口,不是基础设施或数据隐私的限制 库拉姆·贾维德
40:04
灾难性遗忘可以被彻底治好,只要用对算法 理查德·萨顿
42:25
持续学习算法无法套用在现成模型上,必须用它们从头训练新的基础模型 理查德·萨顿
48:40
大实验室被产品绑得太死,走不了先变差再变好的范式转换之路 库拉姆·贾维德
50:46
娴熟运用语言只占智能的约四分之一,语言能力远不等于智能的全部 理查德·萨顿
01「持续学习」本来就是学习
0:00
People think I'm have a radical point of view sometimes. They say they start questions saying how what I'm thinking is so different from everyone else. But I don't see it that way at all. I see it as like I'm thinking the ordinary way. It's just everyone else that's thinking a bit weird. And >> [laughter] >> And I mean that like, you know, it's just the recent times people are thinking weird. Before there was all this AI craziness, uh you talk about you wouldn't have to say continual learning cuz it wouldn't make any sense to talk about learning that wasn't continual. All learning is continual. We always act and we learn. That's just the normal way of thinking. I'm not weird.
有人觉得我的观点有时候挺激进的。他们提问的时候会先说,我的想法跟其他人有多么不一样。但我完全不这么看。我觉得我想的才是常规的方式。只是别人想得有点怪罢了。而且——>> [笑声] >> 我的意思是,你知道,只是最近这段时间大家想得有点怪。在这一波 AI 狂热出现之前,你根本不需要说什么“持续学习”,因为谈论一种不是持续的学习本身就说不通。所有的学习都是持续的。我们总是在行动,也总是在学习。这才是正常的思考方式。不是我怪。
便签引用
0:37
The field is weird. The field they need to call it continual learning. It's just learning.
是这个领域怪。这个领域非要把它叫做持续学习。它就是学习而已。
便签引用
0:50
>> [music]
>> [音乐]
便签引用
02寒冬中投身强化学习的缘由
0:59
>> We are honored to have the great Rich Sutton with us here today. Rich, you invented reinforcement learning. You wrote the seminal textbook. You're the key students in the field, uh folks like Dave Silver. You wrote the essay The Bitter Lesson that I believe is the Bible of the field. And and you have just been one of the greats in propelling the field forward. So thank you for taking the time to join us today. Um Rich is joined by Quorum Javed, his co-founder uh and former students from the University of Alberta.
>> 我们非常荣幸今天请到了伟大的 Rich Sutton。Rich,你发明了强化学习,写下了那本奠基性的教科书。你带出了这个领域里最关键的一批学生,比如 Dave Silver。你写了那篇《苦涩的教训》(The Bitter Lesson),我认为那是这个领域的圣经。而且你一直是推动这个领域向前发展的伟大人物之一。所以非常感谢你今天抽时间来参加。嗯,和 Rich 一起来的还有 Quorum Javed,他的联合创始人,也是他在阿尔伯塔大学的学生。
便签引用
1:28
Um the two of you have set off to found Oak Lab. I'm very excited to talk to you about that today. So for today's session, we're going to start talking about The Bitter Lesson, the state of the world as we know it today, whether LLMs will get us there or not. And then we're going to we're going to transition to start talking about your your research agenda and your plan for Oak. Um Rich, maybe take us back. I was going to start with The Bitter Lesson, but I actually want to start earlier than that. Decades ago, you decided to dedicate your career to reinforcement learning, to deep reinforcement learning in particular, and you established the University of Alberta as a bastion of that back when I think the field was very much in its infancy. What gave you the conviction to do that?
嗯,你们两位一起创办了 Oak Lab。我今天非常期待和你们聊聊这个。那么今天这场对谈,我们先从《苦涩的教训》讲起,聊聊我们今天所认识的这个世界的现状,无论大语言模型能不能带我们到那一步。然后我们会转到讨论你的研究方向,以及你对 Oak 的规划。嗯,Rich,也许我们先回顾一下。我本来打算从《苦涩的教训》讲起,但其实我想从更早的时候开始。几十年前,你决定把职业生涯投入到强化学习,尤其是深度强化学习,并且把阿尔伯塔大学打造成了这个方向的重镇,而那时候我觉得这个领域还处于非常早期的阶段。是什么让你有信心这么做的?
便签引用
2:10
>> What else you going to do? >> [laughter] >> We were trying to figure out the mind and learning is a central part of the mind. And having a goal is a central part of the mind. Central part of intelligence. Yeah, so I was just doubling down on what I was always thinking. >> Did people think you were crazy at the time? >> Um It was a winter. It was an AI winter. >> Uh what year was this? >> It was in 2003. >> Okay. >> And it's kind of crazy actually the truth cuz I was like really sick. I was dying I was actually dying of cancer in 2003. And but I I wasn't quite dead, you know, I've been trying for a number of years. And I wasn't dead after another remission. And so so I said, well, I'm not dying I haven't succeeded in dying. So I might as well, you know, it's going on long enough might as well just try to get another job. And so I so I went to Alberta and and and started teaching there.
>> 不然还能干什么呢?>> [笑] >> 我们当时想搞清楚心智是怎么回事,而学习是心智的核心组成部分。拥有目标也是心智的核心组成部分,是智能的核心组成部分。是啊,所以我只是在我一直以来的想法上加倍下注而已。>> 当时有人觉得你疯了吗?>> 嗯,那是个寒冬,是 AI 寒冬。>> 呃,那是哪一年?>> 是在 2003 年。>> 好的。>> 说来其实挺离谱的,因为我当时真的病得很重。我快死了,2003年我真的差点死于癌症。但我还没死透,你知道,我已经努力了好几年了。又一次缓解之后我还是没死。所以我就想,好吧,我没死成,我没能成功地死掉。那我不如你知道,这都拖了这么久了,不如干脆再去找份工作。于是我就去了阿尔伯塔,在那儿开始教书。
便签引用
3:12
And then in the end I didn't die. It's kind of amazing it's cuz you know, it's it's like that. I'm joking about it now but it was quite serious. And um it's an even more important question. Why why did I continue to work on this research stuff when I was, you know, I only had a few months. I would always keep reminded what I think it's Benjamin Franklin is supposed to have said that, you know, if you ever wonder why someone is doing something it's almost always one of two things. It's either habit or vanity. Okay? So I think I think it's probably true. Maybe it was my habit to just kept doing what I'd always been was doing or maybe it was vanity.
然后到最后我居然没死。挺神奇的,因为你知道,事情就是这样。我现在拿它开玩笑,但当时相当严重。嗯,还有个更重要的问题。为什么我在只剩几个月可活的时候,还在继续做这些研究?我总会想起,我觉得是本杰明·富兰克林说过的一句话:如果你想不通一个人为什么要做某件事,那答案几乎总是两者之一。要么是习惯,要么是虚荣。对吧?我觉得这话大概是对的。也许我只是习惯了继续做我一直在做的事,也许是虚荣。
便签引用
3:52
I I know. I think it was more like habit cuz I was I was dying. >> Wow. >> Um >> Wow. Divine intervention. >> Yeah, it's always been easy for me to keep be very determined. Um and I'm I'm I'm going to go even longer on this answer. >> Please go. >> People think I am have a radical point of view sometimes. They they they start questions saying how how what I'm thinking is so different from everyone else. But I don't see it that way at all. I see it as like I'm thinking the ordinary way. It's everyone else that's thinking a bit weird.
我知道。我觉得更像是习惯,因为我当时都快死了。>> 哇。>> 嗯 >> 哇。神的旨意。>> 是啊,保持非常坚定对我来说一直都很容易。嗯,这个回答我还想再说长一点。>> 请讲。>> 人们有时觉得我的观点很激进。他们提问时会说,我的想法跟别人多么多么不一样。但我完全不这么看。我觉得我的想法才是很平常的那种。是其他所有人想得有点怪。
便签引用
4:24
>> [laughter] >> And I mean that like, you know, it's just the recent times people are thinking weird. If you go look back what what what what people thought about the mind for, you know, even just a decade, you'll find the kind of thoughts that, you know, learning is important. You've got to have a goal. Um and you know, perception is important. We have a We are We are low-level We are low-level beings. We are generating actions and perceiving data at a fast speed and yet we have to think at higher levels. And you know, go back a few before there was all this AI craziness, uh you talk about you wouldn't have to say continual learning cuz it wouldn't make any sense to talk about learning that wasn't continual. All learning is continual.
>> [笑声] >> 我的意思是,你知道,只是最近这些年人们才想得很怪。如果你回头看看以前人们对心智的看法,哪怕只往回看十年,你会发现那些想法是:学习很重要。你得有一个目标。嗯,还有,感知很重要。我们是……我们是低层次的存在。我们以很快的速度产生动作、感知数据,但我们又必须在更高的层次上思考。你知道,回到这一波AI狂热之前,你根本不用说“持续学习”,因为谈论一种不持续的学习是没有意义的。所有学习都是持续的。
便签引用
5:08
You know, you It's not a special phase. We always act and we learn. That's just the normal way of thinking. I'm not weird. The field is weird. The field they need to call it continual learning. It's just learning. >> I'm not weird, everybody else is. That's a good good motto to live by. >> We're going to have to send out a an ex post about that. >> [laughter] >> We're very happy that you you you lived on with the field is happy that you lived on and thank you for pushing the frontier of AI. >> happy.
你知道,它不是一个特殊阶段。我们一直在行动,也一直在学习。这就是正常的思维方式。我不怪。是这个领域怪。这个领域非要管它叫持续学习。它就是学习。>> 我不怪,是其他所有人怪。这个人生信条不错。>> 我们得就这个发条推文。>> [笑声] >> 我们非常高兴你活了下来,整个领域都为你活下来感到高兴,谢谢你推动了AI的前沿。>> 高兴。
便签引用
5:37
>> [laughter] >> Thank you for pushing the frontier of AI. I'm sure really happy and thank you for all of that and push you've like been able to sort of educate a lot of students who pushed the frontier as well. How did you pick them? How did you over the last 20, 30 years? >> Oh, well, you are giving me opportunities to be uh to be humble. Like I like to be humble and point out how all these great decisions are are just happen. And it's that that's the way I feel about students. I don't feel that I choose them very well. I've just Sometimes I'm lucky, sometimes I'm unlucky.
>> [笑声] >> 谢谢你推动AI前沿。我真的很高兴,谢谢你所做的这一切和你的推动,你还培养了很多同样在推动前沿的学生。你是怎么挑他们的?过去二三十年里你是怎么挑的?>> 哦,你这是在给我机会表现谦虚。我喜欢谦虚,喜欢指出所有这些伟大的决定其实都是碰巧发生的。对学生我也是这种感觉。我不觉得自己挑学生挑得多好。我只是……有时候运气好,有时候运气不好。
便签引用
6:10
I don't feel I'm particularly good at picking my students. I'm looking at Karam. I think sometimes you end up with the really great ones. David picked David Silver picked me. >> Yeah. >> How is it that that I got you, Karam? >> Yeah, that was also so I finished my master's not with you uh and I was planning to join industry. And then we were collaborating on a project which also just had started organically. Like there was something I worked on that Rich was in a meeting, then they mentioned that I worked on it.
我不觉得自己特别擅长挑学生。我看着Khuram呢。我觉得有时候你就是会遇上特别出色的。David挑了我——David Silver挑了我。>> 是的。>> Khuram,我是怎么招到你的?>> 是啊,我硕士不是跟你读的,当时我打算去业界。然后我们在一个项目上合作,那也是很自然而然开始的。就是我做过的一些东西,Rich在一个会上,然后有人提到我做过这个。
便签引用
6:40
So I got pulled into it. We started collaborating. It went really well. Like I felt so happy with that collaboration. Rich also felt really good about it. And then 6 months down the road we had made some progress and it just made sense to convert that into a thesis proposal. So at no point did I apply, at no point did I ask should you be my PhD advisor. We worked together, then we decided this would be a pretty good thesis. And then then after that I applied for the PhD. >> Life works in unexpected ways.
所以我就被拉了进去。我们开始合作,进展非常顺利。我对那次合作感觉特别好。Rich也觉得很不错。然后半年后我们取得了一些进展,把它转成一个论文选题就顺理成章了。所以我从来没有申请过,也从来没问过你能不能当我的博士导师。我们一起做事,然后我们决定这会是一个相当不错的论文题目。之后我才去申请了博士。>> 生活总是以意想不到的方式展开。
便签引用
03《苦涩的教训》的精髓与误读
7:10
Uh take us to 2019. You wrote the bitter lesson which has become the the mother in tome. 2019 was a funny time to be writing that piece because ImageNet was 2009. AlphaGo was 2015. What caused you in 2019 to reflect and and to write that? Because it was before the current kind of scaling paradigm around large language models had taken off, but it was after deep learning had really proven itself. >> Well, it was a long time coming. You know, as the bitter lesson expresses, it's something that you can for a long time, for many decades.
嗯,说说2019年。你写了《苦涩的教训》,它已经成为一部圣经般的文本。2019年写那篇文章是个挺有意思的时间点,因为ImageNet是2009年,AlphaGo是2015年。是什么让你在2019年去反思并写下它?因为那时候围绕大语言模型的当下这波扩展范式还没起飞,但深度学习已经真正证明了自己。>> 嗯,这是酝酿了很久的。你知道,正如《苦涩的教训》所表达的,那是一件你长期以来、几十年里都能看到的事。
便签引用
7:45
And it's definitely at least as much due to the round of symbolic AI, which I lived through. It's all about not getting distracted by trying to put in your human knowledge and just paying attention to what the problem needs and how you can scale with computation. I know I I I wrote versions of it at least a year before and I I gave talks. I gave a talk a year before. And um it wasn't a particular response to the moment. It was a particular response to my my long experience, different people trying to think in different ways about how you can make smart systems.
而且它至少同样多地源于我亲身经历过的那一轮符号主义AI。核心就是不要被“往里塞人类知识”这件事分散注意力,而是关注问题真正需要什么,以及你如何能随算力扩展。我知道我至少在那之前一年就写过它的各种版本,我还做过演讲。我提前一年做过一次演讲。嗯,它并不是对某个特定时刻的回应。它是对我长期经历的回应——不同的人用不同的方式思考如何造出聪明的系统。
便签引用
8:28
>> Mhm. What is the essence of the bitter lesson? >> The essence of the bitter lesson. >> You know, and maybe the phrase that I hear used the most in my meetings these days is is bitter lesson pill, is it not bitter lesson pill? I would imagine given the popularity of the phrase it's probably been tortured and misused in different ways that you didn't originally intend it. So, what do you think what is the essence of it and where do you think people go wrong in their in their attempt to understand it?
>> 嗯。《苦涩的教训》的精髓是什么?>> 《苦涩的教训》的精髓。>> 你知道,我最近开会时听得最多的一个说法就是“bitter lesson pill(苦涩教训药丸)”,是不是叫bitter lesson pill?我猜以这个说法的流行程度,它大概已经被各种曲解和误用了,那些都不是你原本想表达的。所以你觉得它的精髓是什么?你觉得人们在理解它的时候错在哪里?
便签引用
8:53
>> Yeah, you're you're making me think about X now and my I recently made a post where I tried to do the the bitter lesson in in 26 words. It [laughter] goes something like don't be distracted by human knowledge as AI traditionally has been many times. Instead focus on learning methods that will scale with computation like search and like learning. So, it's really all about uh focusing on algorithms and improvements. It's not it's not saying you don't need fancy algorithms. You need fancy algorithms, but you want fancy algorithms that will scale with scale with computation.
>> 是啊,你让我想到X了,我最近发了一条帖子,想用26个词把《苦涩的教训》讲清楚。它[笑声]大概是这样:不要像AI传统上一次次做的那样,被人类知识分散注意力。相反,要专注于那些能随算力扩展的学习方法,比如搜索,比如学习。所以它真正讲的是专注于算法和改进。它不是说你不需要精巧的算法。你需要精巧的算法,但你想要的是那种能随算力扩展的精巧算法。
便签引用
9:40
>> Rather than scaling with data. >> Rather than scaling with human input. Yeah, and then the the question if I can anticipate it um Yeah, what about large language models? >> Yeah. >> Are they >> consistent or inconsistent with your >> Yeah. >> And and I thought about this and I think there's an ex- there's another exposed model, but the conclusion is that it's both a a positive example and a negative example of the big lesson. First uh large language models enabled uh enormous scaling with computation. And you could just drink in the internet and scale so much.
>> 而不是随数据扩展。>> 而不是随人类输入扩展。是啊,然后那个问题,如果我能预料到的话,嗯,是啊,那大语言模型呢?>> 是的。>> 它们跟你的观点 >> 是一致还是不一致 >> 是啊。>> 我想过这个问题,我觉得还有一条推文说过这个,但结论是它既是苦涩教训的正面例子,也是反面例子。首先,大语言模型实现了随算力的巨大扩展。你可以把整个互联网喝下去,扩展到非常大的规模。
便签引用
10:20
So it was a it was a way of getting uh much more capable system just by methods that scale. Then after that, as you go on further um it eventually gets limited by by that information. The the internet is finite and it's hard to get more examples. And uh the world is big and the world is massively bigger than everything we stored on the internet. And so in the end, it seems like it could be uh I guess that would be a positive example of when, you know, we relied too much on human knowledge and it eventually holds us back.
所以它是一种仅靠可扩展的方法就获得强得多的系统的途径。但在那之后,随着你继续往前走,嗯,它最终会受限于那些信息。互联网是有限的,很难获得更多样本。而且世界很大,世界比我们存在互联网上的一切都要大得多。所以最终,看起来它可能会是——我想那会是一个正面例子的反面——你知道,我们过度依赖了人类知识,而这最终会拖住我们。
便签引用
04合成数据之争与大世界假说
10:59
>> Mhm. Can I just push on this a little bit? >> Yeah. >> It seems like a lot of what the foundation model labs are working on right now is synthetic data generation in order to kind of get us beyond the fossil fuel that is the existing human internet. Um is synthetic data generation kind of as part of this LLM scaling paradigm, is that a general method that leverages computation? >> No, that's that's just a big mistake. >> Why? >> [laughter] >> Well, it's such a big it's such a maybe it's the next the next big lesson.
>> 嗯。我能就这一点再追问一下吗?>> 可以。>> 现在基础模型实验室们做的很多事情似乎都是合成数据生成,目的就是让我们越过现有人类互联网这块“化石燃料”。嗯,作为这波LLM扩展范式一部分的合成数据生成,它算不算一种能利用算力的通用方法?>> 不算,那就是个大错误。>> 为什么?>> [笑声] >> 呃,这事儿太大了,也许它就是下一个苦涩的教训。
便签引用
11:33
Um it's been floating around uh Alberta for 5 or 10 years. >> Okay. >> And uh we call it the big world perspective or big world hypothesis. Khuram, who eventually wrote it up as a paper. There's a little paper called the big world hypothesis. >> So, the big world is that the world is infinitely big. There are infinitely many things to learn. And you can have people generating the synthetic data sets, but there will always be more things to learn. And because of that, if you could just learn from experience, if you could remove the humans from the loop, then you would have systems that can do everything. Because, you know, the world is big. There are many tasks that we want them to do.
嗯,这个想法在阿尔伯塔已经流传了五到十年。>> 好的。>> 呃,我们把它叫做“大世界视角”或者“大世界假说”。Khuram后来把它写成了一篇论文。有一篇小论文就叫《大世界假说》。>> 所谓大世界,就是世界是无限大的。要学的东西有无限多。你可以让人去生成合成数据集,但永远都会有更多东西要学。正因为如此,如果你能直接从经验中学习,如果你能把人类从回路中拿掉,那你就会有能做任何事的系统。因为你知道,世界很大。我们想让它们做的任务有很多。
便签引用
12:17
And they would be able to do anything by learning from their experience. Going back to the synthetic data question, too. Uh who decides what's a good synthetic data and what's a bad synthetic data? Because I can write a program that can output a lot of synthetic data, which would hurt programs. Right now, I would say humans decide. And that's the bottleneck where okay, you can have humans deciding how to generate these data sets, but you need human experts who know what's a good data set and what's a bad data set for that approach to scale. So, it is bottlenecked by humans.
而它们能够通过从自身经验中学习去做任何事情。再回到合成数据的问题,嗯。谁来决定什么是好的合成数据、什么是坏的合成数据?因为我可以写一个程序,输出一大堆合成数据,那反而会损害程序。就目前来说,我会说是人类在决定。这就是瓶颈所在——好吧,你可以让人类来决定怎么生成这些数据集,但你需要懂行的人类专家来判断什么是好数据集、什么是坏数据集,这种方法才能扩展。所以它被人类卡住了。
便签引用
12:45
>> Doesn't my loss curve decide like how much better did I get with this data set versus that better data set? >> Right. But, if all the engineers open AI and tropic or all the big new labs and engineers went on vacation, who would generate the synthetic data? That's the question. It doesn't doesn't come from agent's experience. It's not something that the agent is generating itself. Some human has to decide what is the right synthetic data to generate. And that requires human expertise. So, for example, if you want a system to do something very challenging from a physics point of view. Maybe you want a drone that flies with echolocation, like a bat, for example. Um what's the right synthetic data for that? I think you would need to hire domain experts to go figure out what is the right data and generate it and then maybe you would be able to learn from that. But the domain expert has to exist first.
>> 难道不是我的损失曲线来决定吗——比如用这个数据集比用那个更好的数据集,我提升了多少?>> 对。但是,如果 OpenAI、Anthropic 这些大型新实验室的工程师们都去度假了,谁来生成合成数据呢?这就是问题所在。它不是来自智能体的经验,也不是智能体自己生成出来的。得有人来决定什么才是该生成的正确的合成数据。而这需要人类的专业知识。比如说,如果你想让一个系统做一件从物理角度看非常有挑战性的事情,比如你想要一架能靠回声定位飞行的无人机,像蝙蝠那样。那么,什么才是对应的合成数据呢?我觉得你得去雇领域专家,让他们搞清楚什么才是正确的数据,把它生成出来,然后你也许才能从中学习。但前提是这个领域专家得先存在。
便签引用
13:35
So, we are bottlenecked by human expertise at that point. >> But you can have infinite synthetic worlds. The existing world is finite. >> But let's go back to the echolocation thing, right? That's what I want. I want a drone that can uh localize itself and move with echolocation. That's my goal. Um the robot that that's a robot that's generating its own experience. So, it could totally learn from its own experience, but it wouldn't be able to It doesn't matter how much synthetic data you generate. Doesn't matter if you generate synthetic data that captures 50 different universes, it will not be not allow you to do that task without humans figuring it out first.
所以到那一步,我们就被人类的专业知识卡住了。>> 但你可以拥有无限多的合成世界。而现有的世界是有限的。>> 但我们还是回到回声定位那个例子,对吧?那就是我想要的。我想要一架能靠回声定位来自我定位、并且移动的无人机。这就是我的目标。嗯,这个机器人——它是一个能生成自身经验的机器人。所以它完全可以从自己的经验中学习,但它没法……不管你生成多少合成数据都没用。哪怕你生成的合成数据涵盖了 50 个不同的宇宙,只要没有人先把这件事搞明白,它就没法完成那个任务。先把这件事搞明白。
便签引用
14:12
>> I first just say it's it's the synthetic data is wrong. I mean, it won't be correct. It'll be a synthetic world. It won't be the real world. And it will matter. The world is incredibly complex. If you write a little program, cuz this is going to be a little program that will generate the synthetic data, it'll be a very It'll be a small world. >> Mhm. >> So, for example, what's important to me is what's going on in your mind right now. Okay? And why You're saying, "Why don't I get some synthetic data to tell me what's going on in other people's minds?" No, there's no way we can have synthetic data for other people's minds.
>> 我首先想说的是,合成数据本身就是错的。我的意思是,它不会是正确的。它会是一个合成的世界,而不是真实的世界。而这是有影响的。这个世界复杂得难以置信。如果你写一个小程序——因为生成合成数据的无非就是一个小程序——那它会是一个非常……那会是一个很小的世界。>> 嗯哼。>> 举个例子,对我来说重要的是你此刻脑子里在想什么。对吧?而你会说:“我为什么不弄点合成数据来告诉我别人脑子里在想什么呢?”不,我们不可能有关于别人心智的合成数据。
便签引用
14:53
And other people's minds matter to us. You know, like I talked to you guys about investing today, so I care what you going on in your minds. And how how can I get synthetic data on such a thing? Really, you can't even get synthetic data on anything. You can't get synthetic data on on the how the drone is going to interact with with its environment in the physical world and the the the the friction and where in the motors of this of this robot. The world is infinitely complex, and any simulation of it is like microscopic. The big world hypothesis, let's say what it is, is that the world is massively more complex than your mind, than any agents any agent.
而别人的心智对我们来说很重要。你看,我今天跟你们聊投资的事,所以我很在意你们心里在想什么。那我怎么可能拿到这种东西的合成数据呢?说真的,你几乎什么都拿不到合成数据。你没法得到关于无人机将如何与物理世界中的环境交互的合成数据,还有摩擦力、这个机器人马达内部的情况等等。这个世界是无限复杂的,任何对它的模拟都只是微不足道的一点点。所谓“大世界假说”,说白了就是:世界远比你的心智复杂得多,比任何智能体都复杂得多。
便签引用
15:37
And this is obvious because the world contains many other agents. So, because the world is is massively complex, as you could no way you can do anything like anything that might claim to be optimal or perfect. You're going to be imperfect, and you have to have approximations, and those approximations will will be severe. And so, because of that, that is the ultimately the reason why we have to continue learning, if you want to think of it as a reason. We have to continue learning because we'll encounter some particular part of this immense world, and we'll have to learn an approximation that's tuned to the part of the world we're in, not to the all the other parts that we're not in.
这一点是显而易见的,因为世界里还包含着许许多多其他智能体。所以,正因为世界极其复杂,你根本不可能做出任何号称最优或完美的东西。你注定是不完美的,你必须依靠近似,而这些近似还会是相当粗糙的。正因为如此,这归根结底就是我们必须持续学习的原因——如果你想把它当作一个理由的话。我们必须持续学习,因为我们会遇到这个庞大世界中某个特定的局部,我们必须学到一个针对我们所处的那部分世界调校过的近似,而不是针对我们没身处其中的其他所有部分。
便签引用
16:19
>> Yeah. I'm I'm going to push on this one more time. Um, and sorry, I'm being argumentative for the sake of being argumentative, [clears throat] but I'm trying to understand. My understanding is that the newest cohort of self-driving car companies, many of them were primarily trained in sim, and then they, you know, have to do some some sort of post-training, I guess, to to make sure they work in the real world, but but that it's been a very effective pipeline. >> Yeah. So, I think the important question to ask here is, how many engineers were involved in building that simulation, and are we ready to say that the only problem worth solving are those where we can hire a large team of engineers to first make a simulation. And I'm sure they had to do multiple iterations where they made the simulation, they learned in it, they realized there was a sim-to-real gap that was not acceptable, then they fixed it. So, there is this human in the loop fixing the simulation.
>> 好。我想再追问一次。抱歉,我有点为了抬杠而抬杠,(清嗓子)但我是想弄明白。据我了解,最新一批自动驾驶公司里,很多家主要是在仿真里训练的,然后再做某种后训练,我想是为了确保它们在真实世界里能работать——能正常工作,但这条路线一直非常有效。>> 是的。所以我觉得这里该问的关键问题是:建这套仿真系统投入了多少工程师?我们是否准备好承认:唯一值得解决的问题,就只有那些我们能雇一大批工程师先做出一套仿真的问题?而且我敢肯定他们必须反复迭代好几轮——先做出仿真,在里面训练,然后发现有个无法接受的仿真到现实的差距(sim-to-real gap),接着再去修。所以这里有一个“人在回路”里在修仿真。
便签引用
17:10
Like, they're getting feedback from the real world, humans, and then they're fixing the simulation. Why can't we just remove the human and let the agent do it itself. >> And then when it actually drives, again, something unexpected will happen. >> And that's when you really want to learn from experience. >> So, your point is there's just so much more data that's going to come from experience than there possibly can be from humans curating and creating data. >> Yeah, and think there is a there is obviously value in learning from simulation. And and there is a way of doing it. The agent can learn a model from its own experience. And when the agent learns it, it's very it's much better because if the model is incorrect, it can fix it by continuous learning.
就是说,他们从真实世界拿到反馈,人来处理,然后去修仿真。那我们为什么不能干脆把人去掉,让智能体自己来做这件事呢?>> 而且等它真正上路开的时候,还是会出现意料之外的情况。>> 而那正是你真正需要从经验中学习的时候。>> 所以你的意思是,来自经验的数据量,远远超过人类去筛选和创造所能提供的数据量。>> 是的,而且我认为从仿真中学习显然是有价值的,也确实有办法做到。智能体可以从自己的经验中学到一个模型。而当智能体自己学到这个模型时,效果要好得多,因为如果模型不正确,它可以通过持续学习来修正。
便签引用
05先验知识与学习本不该为敌
17:49
If the humans are making a simulator, then the model only gets updated when the humans figure out that something is wrong. So, yes, planning is important. The agents should learn from uh simulators, but simulators they make themselves. >> Okay, I want to move to another part of the bitter lesson, removing human knowledge. From your essay, quote, "Seeking the improvement that makes a difference in the shorter term, researchers seek to leverage their human knowledge of the domain. But the only thing that matters in the long run is the leveraging of computation."
如果仿真器是人做的,那模型就只有在人发现哪里出了问题的时候才会被更新。所以,是的,规划很重要,智能体应该从仿真器中学习,但那必须是它们自己造的仿真器。>> 好,我想聊聊《苦涩的教训》的另一部分:去掉人类知识。引用你文章里的话:“为了寻求在较短期内产生效果的改进,研究者往往试图利用自己在该领域的人类知识。但从长远看,唯一重要的是对算力的利用。”
便签引用
18:17
And if I, you know, your former student Dave, uh with AlphaGo and AlphaZero, for me that was a an example of a triumph of removing human priors. Did that result surprise you? I guess why or why not? >> Of course, it made me very happy. It made me, you know, feel vindicated. Um you know, it could have gone either way. It wasn't that uh cuz cuz prior knowledge can help. You know, there's nothing wrong with prior knowledge. You know, and and I say this right at the very beginning of the right at the very beginning of the bitter lesson, I say there's no reason why there has to be a conflict between prior knowledge and then learning knowledge. You know, you can put some prior in there and then start learning.
那么,你以前的学生 Dave(大卫)做的 AlphaGo 和 AlphaZero,在我看来就是一个去除人类先验的胜利案例。那个结果让你意外吗?为什么意外或者为什么不意外?>> 当然,那让我非常高兴。让我觉得自己被证明是对的。不过你知道,事情本来也可能是另一种走向。并不是说……因为先验知识是可以起作用的。先验知识本身没什么不好。我在《苦涩的教训》开头就说过——就在文章最开始——我说没有任何理由说先验知识和后天学到的知识之间必然存在冲突。你完全可以先放一些先验进去,然后再开始学习。
便签引用
18:59
There's no reason in principle why these have to be opposed. In fact, they're all about knowledge. You know, life is gaining knowledge and having knowledge. And why are these how somehow, you know, nature and nurture became enemies? but really you know, prior learning is what you already and then and you then you learn more and it's they should be friends. But, as I say at the beginning of the bitter lesson, in practice they have been enemies. In practice, people who who had a an affection for existing human knowledge ended up, you know, wanting that to win and so they wanted to to minimize or or dismiss learning.
原则上没有理由说这两者必须对立。事实上,它们讲的都是知识。要知道,生命就是在获取知识、拥有知识。那为什么这两者……先天与后天怎么就成了敌人呢?可实际上,先前学到的东西就是你已经掌握的,然后你再学更多,它们本该是朋友。但正如我在《苦涩的教训》开头说的,实际上它们一直是敌人。现实中,那些对既有人类知识怀有偏爱的人,最后会希望那一边赢,于是他们就想弱化甚至否定学习。
便签引用
19:38
And so now, I'm sure your sense of me is that I'm someone who who loves learning and wants to dismiss prior knowledge. Um but you know, I'm really someone who's interested in the mind. The mind is you have prior knowledge and then you get more and then once you've gotten more, then that becomes your prior knowledge as you get more and more and more. And this these two things work together. I end up appearing to be someone who's who's interested in learning primarily because all the rest of the world is is is is talking about all you need is enough knowledge. You don't need to learn.
所以现在,我猜你对我的印象是:我是那种热爱学习、想要否定先验知识的人。但其实,我真正感兴趣的是心智。心智就是:你先有一些先验知识,然后获得更多,一旦你获得了更多,那些就变成了你新的先验知识,如此不断累积下去。这两者是协同工作的。我之所以最后看起来像是主要关注学习的人,是因为世界上其他所有人都在说:你只需要足够的知识,你不需要学习。
便签引用
20:15
You know, large language models are we're going to put all this knowledge in the into the system and the large language model will not learn when it runs. You know, you know, it's talking to people, it's interacting. It is absolutely the weights never change. So, you know, I am not the weird one. It's you guys that are the weird one that think that that's possible that you could possibly, you know, they claim they can like a PhD level experience and expertise out of something that doesn't learn at all anymore.
你看,大语言模型就是——我们要把所有这些知识塞进系统里,而这个大语言模型在运行时是不会学习的。它在跟人对话、在交互,但它的权重绝对是一成不变的。所以你看,怪的不是我。是你们这些认为“那样也行得通”的人才怪,他们声称能从一个已经完全不再学习的东西里,得到博士级别的经验和专业能力。
便签引用
20:44
You know, so you know, I'm not the weird one. >> [laughter] >> So, your recommendation is let it let the algorithms run for much much longer period of time before feeding >> Continually learn. >> before you feed it data. with prior data. So, drip or drip the prior data along the way. prior knowledge. >> So, both are important. Um but in the long run, you've got to gain and structure the gaining of new knowledge. That's that's what all that matters in the long run. And as you are doing this, yeah, there'll be some that you had got previously.
所以说,怪的真不是我。>> (笑)>> 所以你的建议是,让算法先跑很久很久,然后再喂给它>> 持续学习。>> 在你喂数据之前。用先验数据。所以是把先验数据一点一点地滴进去。先验知识。>> 两者都重要。但从长远看,你必须获取新知识,并把获取新知识这件事组织好。长远来看,重要的只有这个。而在你这么做的过程中,是的,会有一些是你之前就已经获得的。
便签引用
21:22
Um, like how it would work if we, you know, look into the future when we have intelligent robots. We will we will will we uh, have them all learn from scratch? Or will we like copy them and ask them to keep learning from wherever they are? I mean, we they'll be digital and it'll be easy to copy them. And so, instead of having like this huge thing where we're spending zillions of dollars to retrain them from the internet, we'll just copy the agent and keep learning from there. And and so, in some sense, the prior knowledge will be should be dismissed cuz you're just going to copy it from the previous robot.
比如说,我们可以设想一下未来有了智能机器人之后会怎么运作。我们会让它们全都从零开始学吗?还是我们会直接复制它们,让它们从当前的状态继续学下去?我是说,它们是数字化的,复制起来很容易。所以,与其搞那种花上天文数字的钱、从互联网上重新训练一遍的大工程,我们不如直接复制那个智能体,从那儿继续学下去。所以在某种意义上,先验知识应该被搁到一边,因为你只要从上一个机器人那里复制过来就行了。
便签引用
06权重不变的 LLM 算学习吗
22:02
>> So, why don't you describe for us what you think a machine or computer that learns from experience looks like? >> Well, it could look like a robot. It could be It also could be live entirely on the internet. You could like, for example, routing a package through the internet and do that in a way that's sensitive to experience and and becomes better over time. Or you can interact via the user interface that's interacting with people, like on your phone or on your computer, and uh, it becomes better over time. Yeah, like an intelligent assistant, you know, has to become better over time. It has to know what you want.
>> 那你能不能给我们描述一下,你认为一台从经验中学习的机器或计算机是什么样子的?>> 嗯,它可以是一个机器人的样子。也可以完全生活在互联网上。比如说,在互联网上路由一个数据包,并且以一种对经验敏感的方式来做,从而随着时间推移变得越来越好。或者它可以通过用户界面与人交互,比如在你的手机上或电脑上,然后随着时间推移变得越来越好。是的,就像一个智能助手,它必须随着时间变得更好。它得知道你想要什么。
便签引用
22:37
>> Would your contention be that the current paradigm of, you know, the popular A L M based assistants, would your contention be that these are not experiential learners or continual learners? And if so, what is the fundamental gap? >> Are you serious? >> [laughter] >> I mean, obviously they >> They they have memo- they learn memories about me. They're you know, they're they're they're doing some in-context learning. >> Their weights never change. >> And and by the way, is a small number of the weights changing sufficient or do you need all the weights to be changing?
>> 你的观点是不是说,当前这种流行的基于大语言模型的助手范式,你是不是认为它们并不是从经验中学习的学习者,也不是持续学习者?如果是的话,根本性的差距在哪里?>> 你是认真的吗?>> (笑)>> 我是说,显然它们……>> 它们有记忆——它们会记住关于我的事情。它们,你知道的,它们在做某种上下文内学习(in-context learning)。>> 它们的权重从来不变。>> 另外顺便问一句,只有一小部分权重发生变化就够了吗?还是需要所有权重都在变化?
便签引用
23:10
>> Well, so all think of all the structuring and generation of new concepts that went into creating the large language models. All that is the weight learning. The and you you want to continue be able to continue doing that. You don't want that to happen just once. >> Is another way of saying it is we do too much pre-training and post-training before we launch the the models. They they don't learn after that. >> The only point that the big disagreement is we don't let them learn after that. >> Yeah, we don't let them learn after that.
>> 嗯,想想为了创造出大语言模型,投入了多少新概念的构建和生成。所有这些都属于权重学习。而你希望能够继续做这件事。你不希望它只发生一次。>> 换一种说法就是,我们在发布模型之前做了太多预训练和后训练。它们在那之后就不再学习了。>> 唯一有大分歧的地方是,我们不让它们在那之后继续学习。>> 是的,我们不让它们在那之后继续学习。
便签引用
23:40
>> as much pre-training as we want, that's okay. Post-training is fine, but then when I'm when I'm using the model I cannot it's it's it stops learning. Uh you can give it more context. You can change the state of the model by giving it more context. And so it it already learned that if the state is different, if the state says something new, then it will use that to make the next prediction. But the model is not learning. >> Cursor's tab other complete model. It is, you know, it does get updated based on >> Those models those weights change.
>> 想做多少预训练都行,没问题。后训练也没问题,但当我在使用这个模型时,我没法……它就停止学习了。呃,你可以给它更多上下文。你可以通过给它更多上下文来改变模型的状态。所以它其实已经学会了:如果状态不同,如果状态里出现了新的信息,它就会用这些信息来做下一步的预测。但模型本身并没有在学习。>> Cursor 的 tab 补全模型,它确实会根据……来更新 >> 那些模型的权重是会变的。
便签引用
24:09
>> weights change. Those are two examples like Cursor's tab and I think the composer they were also updating. Those are two examples of continual learning. >> Okay. >> it's can be much better. So the way they do it as far as I understand is a lot of people are using tab, they collect all this data so coming from millions of users or thousands of users and then they do one update of the policy from this batch data. Um so now this could work, but imagine I want to teach this model something specific. I don't want to fight with 100,000 other peoples about what they want to treat teach their models. I want to teach my model something very specific and I want to do it to my version of the model. I like I don't care about the shared knowledge that the model has coming from other people.
>> 权重会变。这就是两个例子,比如 Cursor 的 tab,我想 composer 他们也在更新。这就是持续学习的两个例子。>> 好的。>> 其实可以做得好得多。据我理解,他们的做法是这样:很多人在用 tab 补全,他们把所有这些数据收集起来,来自几百万或者几千个用户,然后用这批数据对策略做一次更新。嗯,所以这是可行的,但想象一下我想教这个模型某个特定的东西。我不想跟另外十万个人去争,去争他们各自想教自己模型的东西。我想教我的模型一些非常具体的东西,而且我想把它教给我自己那个版本的模型。我并不在乎模型从其他人那里获得的那些共享知识。
便签引用
24:48
And so it's a very inefficient way of doing it. >> Mhm. It seems like the way that this is currently done is that there's fundamental skills maybe that are learned in the weights that are common to everybody. And then there's personalization that happens in the form of context, right? >> Yeah. >> Is that not the right mental model for how learning should work? Like should should all the context live in the weights themselves? >> So, context can be in the state, too. Could be both. But, you still need to be able to update the weights. So, if I give you an example, some really good use studies are for with human disabilities. When human go through something that changes their mind or or some sensors, you can see them adapt.
>> 所以这是一种非常低效的做法。>> 嗯。看起来目前的做法是,有些基础能力可能是学在权重里的,是所有人共通的。然后个性化是以上下文的形式发生的,对吧?>> 是的。>> 这个心智模型是不是不对?学习本该是什么样的?是不是所有的上下文都应该存在权重本身里?>> 所以,上下文也可以存在于状态里。两者都有可能。但你仍然需要能够更新权重。举个例子,一些非常好的研究案例来自于人类的残障情况。当人经历了某些改变心智或某些感官的事情时,你能看到他们逐渐适应。
便签引用
25:28
So, for example, we have proprioception, we have internal sensors that tell us where the how the body is positioned, and we use this for walking. There are cases where people lose this ability completely, and then they can't walk at all because that is literally the foundation of their walking policies. It is ingrained in the brain. But then over the course of 2 3 years, they can learn to walk again by looking at their feet. So, visual feedback through that. So, brain is insanely plastic in the sense that it it can learn a lot of things. Something that has been true for 20 years, when it stops being true, it can go and update that and get rid of that. And that is the capability I think that's extremely useful we would want in our systems.
比如说,我们有本体感觉,我们体内有传感器告诉我们身体处于什么位置、姿态如何,我们走路时就靠这个。有些情况下,人会彻底失去这种能力,然后他们就完全没法走路了,因为这实在是他们行走策略的根基,它是刻在大脑里的。但在接下来的两三年里,他们可以通过看着自己的脚重新学会走路。也就是靠视觉反馈来完成这件事。所以大脑的可塑性强得惊人,它能学会非常多的东西。有些事情已经成立了二十年,当它不再成立时,大脑可以去更新,把它抛弃掉。我认为这种能力是极其有用的,是我们希望在自己的系统里拥有的。
便签引用
07动物不靠监督学习,学校无关本质
26:09
>> Hm. What is there for us to learn from how human babies or animals learn? And how much inspiration do you take from that? >> Well, we take uh a lot of inspiration. We don't take it as a requirement that the AI has to behave like uh the natural system, like babies or people or animals. Um but it's it's a source of inspiration. Inspiration, but not constraint from animal learning. >> Consistent with the better lesson? >> Yeah. >> [laughter] >> Yeah. >> Where do you think we should most seek to draw inspiration from the way that biological learnings works that is not present in today's systems?
>> 嗯。人类婴儿或者动物的学习方式,有什么值得我们借鉴的?你从中汲取了多少灵感?>> 嗯,我们确实汲取了很多灵感。我们并不要求 AI 必须表现得像自然系统那样,比如像婴儿、人或者动物。但它是一个灵感来源。是灵感来源,但动物学习并不构成约束。>> 这和「更好的教训」(better lesson)是一致的吗?>> 是的。>> [笑声] >> 是啊。>> 你觉得在生物学习的机制里,有哪些是今天的系统里没有的、最值得我们去汲取灵感的?
便签引用
26:48
>> I feel like I'm just giving opinions now, but they're just obvious opinions. So, so I think it's apparent that no animal learns by supervised learning. Because we don't get examples of how our muscles should twitch. And that's our output. >> But all of school is supervised learning. >> I I know. Absolutely not. Uh, but even if it was, school is like a tiny fraction of what we learn. Like we learn to see, we we learn to walk. And we learn, um, how the world works. But even Yeah, and even in school, you know, no one tells us how we should twitch our muscles.
>> 我感觉我现在只是在发表观点,不过都是些显而易见的观点。我觉得很明显,没有任何动物是靠监督学习来学习的。因为我们不会得到关于自己肌肉该怎么抽动的样例。而那才是我们的输出。>> 可整个学校教育不就是监督学习吗?>> 我知道。绝对不是。呃,就算它是,学校也只占我们所学内容的极小一部分。比如我们学会看东西,我们学会走路。我们学习,嗯,世界是怎么运作的。但就算是在学校里,你知道,也没有人告诉我们该怎么去抽动我们的肌肉。
便签引用
27:31
>> The knowledge skills I acquire were were from supervised learning in school. >> don't want to say that that that learning from from others, transmission from others, is not important. It's like extremely important. And language is extremely important. Um, but what are we what are we missing? You know, there is there is no supervised learning. There's no targets that are given to us. You know, you you hear the right answer is, you know, where where is what's the capital of France? And we know the answer is Paris.
>> 我掌握的知识和技能是在学校通过监督学习获得的。>> 我不想说从别人那里学习、从别人那里传递知识不重要。它极其重要。语言也极其重要。嗯,但我们缺了什么呢?你知道,其实并不存在监督学习。没有人给我们目标答案。你会听到正确答案,比如说,法国的首都是哪里?我们知道答案是巴黎。
便签引用
28:05
Okay, but no one tells me how I should pronounce Paris. You say the answer is Paris, and I listen to you, and I hear your words, and, you know, I will make some other uh, muscle motions to produce the answer Paris. It's not literally supervised learning. Um, anyway, yeah. So, I think it's really true. I mean, well, anyway, the first thing is a school is is irrelevant. Like, you know, squirrels don't go to school and and and learn [laughter] that. >> They might. >> Animals don't learn that way. It's And school is a very special thing that that even we didn't have up until, you know, I don't know, a few hundred years ago.
好吧,但没有人告诉我该怎么发出「巴黎」这个音。你说答案是巴黎,我听着你说,我听到你的话,然后,你知道,我会做出一些别的肌肉动作来说出「巴黎」这个答案。这并不是字面意义上的监督学习。嗯,总之,是的。我觉得这真的没错。我是说,反正首先一点是,学校是无关紧要的。你知道,松鼠可不会去上学,然后学会那些东西。[笑]>> 它们说不定会呢。>> 动物不是那样学习的。学校是一种非常特殊的东西,甚至连我们自己在过去也没有,你知道,我也说不好,也就几百年前才有。
便签引用
28:46
It's not part of in not part of the essence of intelligence? And it's a distraction to think of that as your primary example of learning is this thing which we didn't do as animals. >> I wish you had been around to tell my parents that before I was made to have good go to school and deal with all the structure. >> The thing is like squirrels are wonderful at jumping off trees, but squirrels can't prove math theorems. And if I want to learn how to prove a math theorem, I go to school. >> Yeah. Uh they also don't have uh DVDs and >> [laughter] >> and iPods. You know, there are a lot of things they can do things that we can't do.
它并不是智能本质的一部分?把这种我们作为动物本来并不做的事情,当成学习的主要范例,这其实是种误导。>> 真希望当年你在场,能在我被送去上学、应付那一整套条条框框之前,跟我爸妈说说这些。>> 问题是,松鼠特别擅长从树上跳下来,但松鼠证明不了数学定理。而且如果我想学怎么证明一个数学定理,我就得去上学。>> 是啊。呃,它们也没有 DVD 和 >> [笑] >> iPod。你知道,有很多事它们能做,而我们做不了。
便签引用
29:25
Um but >> [sighs] >> math theorems uh Yeah, and they don't play chess. You know, it's sort of like more of X paradox. They're uh they're these advanced things that we think of as really intelligent. But uh they're sort of easy for computers to do as opposed to all these regular things that are hard. Like moving and seeing with attention and everything. Um I think supervised learning is a is a good thing. You know, just mentions I like to think look for obvious things. No one tells us how to twitch our muscles by giving us examples cuz they couldn't possibly cuz we have had to twitch our muscles. We've had to figure that out.
嗯,但是 >> [叹气] >> 数学定理嘛,是的,而且它们也不下棋。这有点像莫拉维克悖论。呃,有些高级的东西我们觉得非常需要智能,但对计算机来说其实挺容易的,反倒是那些日常的事情很难。比如带着注意力去移动、去看,诸如此类。嗯,我觉得监督学习是个好东西。你知道,顺便提一下,我喜欢找那些显而易见的事情。没有人通过给我们示例来教我们怎么抽动肌肉,因为他们根本做不到,因为我们必须自己去抽动肌肉。我们必须自己把这件事琢磨出来。
便签引用
30:06
>> Yeah. >> And their answer would be wrong, right? So, if I moved my mouth and my tongue and my vocal cords exactly the same way that Rich does to pronounce Paris, I'm sure a very different sound would come out. So, in some sense Rich or no one knows the right way of producing a sound with my body. Only I know that. >> Yeah. It seems to me that many of the most, I guess the most raw like sensory motor capabilities, especially related to movement in the physical world. I agree with you that that seems something that is inherently learns from experience.
>> 是啊。>> 而且他们给的答案会是错的,对吧?所以,如果我用和 Rich 完全一样的方式来动我的嘴、舌头和声带去念「巴黎」,我敢肯定发出来的会是完全不同的声音。所以从某种意义上说,Rich 也好,谁也好,都不知道用我的身体发出声音的正确方式。只有我自己知道。>> 是啊。在我看来,很多最原始的、我想说是最基础的感知运动能力,尤其是和在物理世界中运动相关的那些,我同意你说的,那似乎本质上就是从经验中学来的。
便签引用
30:39
It seems to me though that there are higher levels of abstraction that bring us closer to, you know, what makes humans great. And much of that doesn't live in this low level of sensory motor learning. Does your world model, I guess, span sensory motor learning all the way up? >> Yeah, that's the ambition, absolutely. And squirrels, by the way, can do some enormously abstract things. >> What's the coolest thing a squirrel can do? >> Well, it can always get into your bird feeder, >> [laughter] >> no matter what obstacles you put in the way, you know, it can find new ways to jump and climb and >> Okay.
但在我看来,还有一些更高层次的抽象,它们更接近于,你知道,是什么让人类如此了不起。而其中很多东西并不存在于这种低层次的感知运动学习里。我想问,你的世界模型是不是从感知运动学习一路涵盖到最上层?>> 是的,这正是我们的目标,绝对是。顺便说一句,松鼠也能做一些极其抽象的事情。>> 松鼠能做的最酷的事情是什么?>> 嗯,它总能钻进你的喂鸟器,>> [笑] >> 不管你在路上设多少障碍,你知道,它总能找到新办法去跳、去爬,还有 >> 好吧。
便签引用
31:14
>> and do lots of things. >> Calculate trajectories pretty well. Animals are pretty good at understanding the physical world without the mental calculations that we think we are doing when we think about launching ourselves into space. >> Breaking a fall, they can do it in real time in the right way to prevent injuries. >> Okay, fair enough. >> I think it's just a question of degree between and I like to think that animals, other animals, are are very close to humans. I think it's hubristic to try to emphasize what we do differently, you know, how we're different from animals.
>> 还有做很多别的事情。>> 弹道轨迹算得还挺准。动物很擅长理解物理世界,而不需要我们以为自己在做的那些心算,比如当我们想着把自己发射到空中的时候。>> 化解一次摔倒,它们能实时地用正确的方式做到,避免受伤。>> 好吧,有道理。>> 我觉得这只是程度上的差别,而且我倾向于认为动物,其他动物,和人类非常接近。我觉得一味强调我们有什么不同、我们和动物有什么区别,是种自大。
便签引用
08造火箭需要的想象从哪来
31:48
It's better to see the commonalities. And I I think we are just a question of degree. It's degree and of course society and culture give us big advantages. Language give us big advantages. >> Can I just push on some of this? >> Yeah, good. >> Because I want to back up Sonia. So, I believe animals and children learn from experience and do incredible things learning from experience. And when my son was two or three or four, I'm like, "Wow, this is really interesting that they're my son can learn these things without nobody really teaching him how to do these things."
更好的做法是看到共通之处。而且我觉得我们只是程度上的差别。是程度的问题,当然社会和文化给了我们巨大的优势。语言也给了我们巨大的优势。>> 我能就这点追问一下吗?>> 好的,请。>> 因为我想给 Sonia 补充一下。我相信动物和小孩确实是从经验中学习的,而且能通过从经验中学习做出很了不起的事情。>> 我儿子两三岁、三四岁的时候,我就想:"哇,这真有意思,我儿子居然能学会这些东西,根本没有人>> 真正教过他怎么做这些事。"
便签引用
32:25
But at the same time, what Sonia's saying is like what makes human uniquely human, to be able to go to outer space, build a rocket. Those Those not things that are learned 100% from experience because before you launch the rocket, you actually have to abstract thinking through it in a way that is not learned from {quote} {unquote} experience. Because you don't know if it's going to work or not. You have to imagine it. How do you we teach a machine to imagine things that were not available before? That's probably the thing that we're trying to like push on because that we're not quite understanding that.
>> 但与此同时,Sonia 说的是,人之所以为人的独特之处,是能够进入太空、造出火箭。>> 这些并不是 100% 从经验中学来的东西,因为在你发射火箭之前,>> 你其实必须以某种抽象的方式把它想清楚,而那种方式并不是从所谓的"经验"中学来的。>> 因为你并不知道它到底行不行。你得先想象出来。那我们要怎么教一台机器去想象>> 此前并不存在的东西?这大概就是我们想要追问的地方,因为这一点我们��没完全弄明白。
便签引用
33:04
>> actually going to agree with you there. You have to be able to plan. You have to be able to imagine. >> Yeah. >> Would you say that humans 1,000 years ago, before they had done all most of the thing that we're talking about, were they as intelligent? Um if for example someone from that era was exposed to this new culture, would they be able to get the same skills and and start doing useful things? >> Even over the last 10,000 years, I don't think the human brain has evolved that much. Because >> Fundamentally the same machine.
>> 这一点我其实同意你。>> 你必须能够做规划,必须能够想象。>> 是的。>> 那你会认为一千年前的人类,在他们还没做出我们现在讨论的这些事情之前,>> 他们同样聪明吗?>> 比如说,如果把那个年代的人放到今天这种文化环境里,他们能不能学会同样的技能,>> 然后开始做出有用的事情?>> 就算把过去一万年算进来,我也不认为人脑进化了多少。因为——>> 本质上是同一台机器。
便签引用
33:33
>> Fundamentally the same machine, but we've built up 10,000 years of knowledge. >> Yes. >> And I get to learn 10,000 years of knowledge by going to school through supervised learning. >> Right. >> And I get all that much, much faster than trying to learn through experience. >> Right. >> So I think you're like totally right. So we we would want our systems to learn from experience and part of their experience would be getting exposed to our culture and then learning from about our culture. They should learn from that. That's all good. But let's talk about when someone goes and does a paradigm shifting thing. So everyone gives the example of Einstein, but I think there are many examples. Learning is that too, like looking at learning thing versus programming thing.
>> 本质上是同一台机器,但我们积累了一万年的知识。>> 对。>> 而我可以通过上学、通过监督学习,去学到这一万年的知识。>> 没错。>> 而且我获得这一切的速度,要比试图从经验中学习快得多。>> 对。>> 所以我觉得你说得完全对。我们确实希望我们的系统能从经验中学习,而它们经验的一部分>> 就是接触我们的文化,然后从我们的文化中学习。它们应该从>> 那里学习,这都没问题。但我们来聊聊有人做出范式转变的时候。大家都会举爱因斯坦的例子,但我>> 觉得例子还有很多。学习本身也是这样,比如"学习"这条路线和"编程"这条路线的对比。
便签引用
34:14
So when these paradigm shifts happen, I would say it's a human who has accumulated all this knowledge and then from their experience they're building new abstractions and they're planning with them and then they're discovering new knowledge. And that skill of of coming up with new abstractions and then learning what models and planning with them, that problem is that skill is totally missing in our current systems. And you can expose this at the edge of human knowledge, but you can also study this problem at the sensory motor stream level.
>> 所以当这些范式转变发生时,我会说,是一个人积累了所有这些知识,然后从他自己的经验里>> 构建出新的抽象,并用这些抽象来做规划,进而发现新的知识。而这种能力——>> 提出新的抽象、学到相应的模型并用它们做规划——这个问题、这个能力,在我们现有的系统里>> 是完全缺失的。>> 你可以在人类知识的边界上看到这个问题,但你也可以在感觉运动流的层面上>> 研究这个问题。
便签引用
34:41
>> So, we're not arguing with the with the principle. We need to form abstractions so we can reason at a high level. You guys are coming close to doing that thing that I said we should never do, which is argue is prior knowledge important or gaining knowledge important. You know, that's what you guys just said. You said It's a you're you're still going to have to learn things. And you're saying, "Oh, I can get things from my culture and from prior knowledge." But these should not fight for each other.
>> 所以我们并不是在反对这个原则。我们需要形成抽象,这样才能在高层次上做推理。>> 你们俩现在快要做我说过我们永远不该做的那件事了,>> 也就是去争论到底是先验知识重要还是获取知识重要。你看,你们刚才说的就是这个。你说这是>> 你还是得去学东西。而你说:"哦,我可以从我的文化、从>> 先验知识里获得这些。">> 但这两者不该互相对立。
便签引用
35:10
>> On the exact thing around paradigm shifts, how do we create a machine that understands when to shift the paradigm? >> Yeah, I think through its experience, right? So, it would have to through its own experience. It can't rely on human knowledge because we're assuming the humans see one paradigm and we want a different way of looking at things. And so, through its experience, it has to find something that is better. Maybe it it generalizes better and makes better predictions. Maybe it's better in some other ways, but it has to be through its own experience.
>> 就范式转变这个具体问题而言,我们怎么才能造出一台机器,让它知道什么时候该转变范式?>> 是啊,我觉得是通过它自己的经验,对吧?所以它必须通过自己的经验来做到。它不能依赖人类知识,因为我们>> 假定人类看到的是一种范式,而我们想要一种不同的看待事物的方式。>> 所以,通过它自己的经验,它必须找到某种更好的东西。也许它泛化得更好,做出的>> 预测更准。也许它在别的方面更好,但这必须来自它自己的经验。
便签引用
35:40
>> The big challenge that we don't see in our field, the ability we don't see in our field yet, is the ability to learn a model and then plan with the model. We can do the the math things and we can do AlphaGo because the games, we know the model. We know how the moves work. And in math, we know what the operators are. We you know, we know lean will take us from one state of knowledge to the to the state of the proof to the next state. But if we have to learn the models, there are no I'm I'm going to say it. It's probably maybe a a weird example, but a counterexample, but I can see that there's no instances of learning the model and then planning with the model in our field.
>> 我们这个领域目前还看不到的一大挑战、一项还不具备的能力,就是先学出一个>> 模型,然后用这个模型做规划。>> 我们能做数学那类事情,也能做出 AlphaGo,因为在那些游戏里,模型是已知的。我们知道每一步棋是怎么走的。>> 在数学里,我们知道算子是什么。>> 我们知道,Lean 会带我们从一个知识状态走到证明的下一个>> 状态。>> 但如果我们必须去学习这些模型,那就没有——我就直说了,这可能是个有点奇怪的例子,或者说>> 是个反例,但我看不到在我们这个领域里有任何"先学出模型、再用模型做规划">> 的实例。
便签引用
36:23
>> At least not with uh uh, like self-discovered abstractions. So, there are people who say, "I'm just going to learn a model of what happens in the next second or next millisecond." But, that's not how our models work. Our models are more abstract. Our models are, uh, quite different. >> So, one of the things I like about what you're doing here is you're not just sitting around pontificating or lamenting the state of the world as it is. You're very action-oriented. It's why you started a company. So, let's let's start talking about that a bit.
>> 至少在自己发现抽象这一点上是没有的。所以,>> 有些人会说:"我就学一个关于下一秒或下一毫秒会发生什么的模型。">> 但我们的模型不是那样工作的。我们的模型更抽象。我们的模型>> 相当不一样。>> 所以,我喜欢你们在这里做的事情的一点是,你们不只是坐在那里空谈或者感叹世界现状如何如何。你是非常行动导向的人。所以你才创办了公司。那我们就从这个话题开始聊起吧。
便签引用
09阿尔伯塔计划与灾难性遗忘的解药
36:54
Uh, in 2022, Rich, you laid out a very specific 12-point plan, the Alberta plan for AI research. Maybe tell us about that. >> So, the Alberta plan came about because we just have general ideas, but we also needed to convert them into smaller chunks. And so, the 12 steps are the attempt to uh, crystallize particular chunks. There's a very important early step, step two, uh, which is continual deep learning. And And we think that one is like almost the most important because it unlocks everything else. If you could do continual deep learning, you could then continually update your model of the world.
呃,2022年,Rich,你提出了一个非常具体的十二点计划,也就是人工智能研究的「阿尔伯塔计划」。能给我们讲讲这个计划吗?>> 阿尔伯塔计划的由来是这样的:我们只有一些笼统的想法,但我们还需要把它们拆解成更小的模块。所以这十二个步骤就是试图把一个个具体的模块给明确下来。其中有一个非常重要的早期步骤,也就是第二步,呃,就是持续深度学习(continual deep learning)。我们认为这一步几乎是最重要的,因为它能解锁其他所有的东西。如果你能做到持续深度学习,你就能持续更新你对世界的模型。
便签引用
37:39
And then, if you knew how to do the abstraction rights in like the second half of of the the steps are all about how to get the abstractions right. So, and not only my abstractions right, what I mean by I don't mean get the right abstractions cuz no one can say what the right abstractions are. That depends on the world that you're in. Your agent would have to learn the correct abstractions for whatever world it's in. And so, you know, if you maybe those are the two key things. You have to find the right abstractions, and then you have to do able to continual deep learning.
然后,如果你还知道该怎么把抽象做对——后半部分的那些步骤基本上都是在讲怎么把抽象做对。所以,我说的不只是「我的抽象要对」,我的意思是——我说的并不是要找到「正确的抽象」,因为没人能说清什么才是正确的抽象。那取决于你所处的世界。你的智能体必须自己去学习,在它所处的那个世界里什么才是正确的抽象。所以,你知道,也许这就是两个关键点。你必须找到正确的抽象,然后你必须能够做到持续深度学习。
便签引用
38:10
>> I think that a lot of the people in the field realize that we need models, we need to plan with them. But, the abstractions tell us what the model should be conditioned on. So, what should you What should the model predict? What are you going to do and then something is going to happen. And more importantly, where would that come from? So, I really like the example of elite athletes. If you ask elite athletes about how they do certain things, they would have weird niche terminologies for doing very specific things. They were like, you know, I do this thing and they would have a name for it. If they communicate, sometimes they don't even have a name for it if they're just doing it alone.
>> 我认为领域内很多人都意识到我们需要模型,需要用模型来做规划。但是,抽象告诉我们模型应该以什么为条件。也就是说,模型应该预测什么?你要做什么,然后会发生什么。更重要的是,这些东西从哪儿来?所以我特别喜欢一个例子,就是顶尖运动员。如果你问顶尖运动员他们是怎么做某些事情的,他们会用一些很奇怪、很小众的术语来描述非常具体的动作。他们会说,你知道,我做这个动作,然后他们会给它起个名字。如果他们需要交流的话,有时候如果只是自己一个人练,他们甚至都没有给它起名字。
便签引用
38:45
So, how did they come up with those abstractions? That's in some sense a crucial thing that's missing that the later half of Alberta plan answers. >> Can we talk about the continual deep learning part? Is it an algorithmic gap that exists today or is it a just a practical deployment infrastructure data privacy gap? Because if I wanted to do call it naive updating of weights based on user interaction, I can do that today, right? And so, what in your opinion is the biggest thing that we're missing to kind of get to continual deep learning?
那么,他们是怎么想出这些抽象的?从某种意义上说,这正是目前缺失的关键一环,而《阿尔伯塔计划》的后半部分回答了这个问题。>> 我们能聊聊持续深度学习那部分吗?这在今天是一个算法上的缺口,还是仅仅是实际部署的基础设施、数据隐私方面的缺口?因为如果我想做那种基于用户交互对权重进行朴素更新的做法,我今天就能做,对吧?所以,在你看来,要实现持续深度学习,我们最欠缺的是什么?
便签引用
39:18
>> Yeah, so it's absolutely an algorithmic gap. You You can do the naive thing, but then you'll see all sorts of problems. So, for example, if you say um I'm going to take one sample and then I'm going to update my whole model with that one sample. You will run into this problem that now all of the previous knowledge in the model it's impacted negatively. And the way currently we we get around this is exactly what cursor does. They don't use one example. They use a large batch coming from a lot of users. So, in use cases where you can have that, you can do continual learning. But, most use cases you don't have that. Most use cases you have a single stream of data. And then if you apply it to the naive thing, it just completely destroys your prior knowledge in a very um destructive way.
>> 是的,这绝对是一个算法上的缺口。你可以用那种朴素的做法,但接着你就会看到各种各样的问题。比如说,如果你说,我要拿一个样本,然后我要用这一个样本去更新我的整个模型样本。你就会遇到这样的问题:模型里之前学到的所有知识都受到了负面影响。目前我们绕开这个问题的办法,正是 Cursor 在做的事。他们不用单个样本,而是用一个来自大量用户的大批量数据。所以在那些你能拿到这种数据的场景里,你可以做持续学习。但大多数场景下你没有这个条件。大多数场景下你只有单一的数据流。这时候如果你用那种朴素的做法,它就会彻底摧毁模型原有的知识,而且是以一种非常具破坏性的方式。
便签引用
40:00
>> Catastrophic forgetting. >> Yeah. >> That is the Yeah. >> But, it's totally curable. You have to [laughter] have the right algorithm. >> cure? >> Well, yeah, exactly. >> What is the cure? >> Well, you know, first you need to do what we call step size optimization. And it means every weight in your network has to have a separate step size. So, some will move fast, some will move slow. And you will we you will have to metalearn the step sizes for each weight. Most of your network will be have have weights that have tiny step sizes. So, then when you train on a new example, they don't get destroyed.
>> 灾难性遗忘。>> 是的。>> 那就是 是的。>> 但这完全是可以治好的。你得有 [笑] 对的算法。>> 治好?>> 嗯,对,正是如此。>> 那解药是什么?>> 嗯,你知道,首先你得做我们所说的步长优化。意思是你网络里的每一个权重都得有各自独立的步长。所以有些会变化得快,有些会变化得慢。而你需要为每个权重去元学习(metalearn)这些步长。你网络里的大部分权重的步长都会非常小尺寸。这样当你在新样本上训练时,它们就不会被破坏。
便签引用
40:37
Happens just to the right places. And then secondly, you have to use some form of generate and test. Um which is in feature space. So, you come up with new features or new units and and without following gradients. Cuz gradients are very slow process. You only move in a direction if you know it's the helpful one. And that's always going to be very slow and doesn't give you a path to grow more and more complex and and to have sustained learning. You need to have something that just proposes a bunch of new units.
恰好发生在正确的地方。其次,你必须使用某种形式的生成与测试(generate and test)。嗯,是在特征空间里进行的。也就是说,你提出新的特征或新的单元,而且不遵循梯度。因为梯度是一个非常慢的过程。只有当你知道某个方向是有帮助的,你才会朝那个方向移动。这总是会非常慢,也没法让你走向越来越复杂、实现持续学习。你需要有某种东西,能直接提出一大批新的单元。
便签引用
41:12
And and and then goes from there. I guess so, there is a specific thing I can say that make it at least concrete, which is to say we have this algorithm called continual backprop. We used published in in nature a couple years ago. And it it is exactly like backprop, but every but you also plant new seeds of units that are newly initialized with random weights. Backprop only has random weights at the beginning of time. And then as you go on, all that randomness all that variety from the randomness gets used up.
然后从那里继续下去。我想,有一件具体的事情我可以说,至少能让它变得具体一些,那就是就是说,我们有一个叫做持续反向传播(continual backprop)的算法。我们几年前在《自然》上发表过。它跟反向传播完全一样,只不过你还会不断播下新的种子,也就是用随机权重重新初始化的新单元。权重。反向传播只在最开始的时候有随机权重。然后随着训练进行,所有那些随机性、所有那些多样性都会被随机性消耗殆尽。
便签引用
41:46
And with continual backprop, we keep injecting a bit of randomness, a bit of generate and test, a bit of generate and then the the operation of backprop is the tester. So, you need you need that. And and if you put those together really well, I think you'll have a new generation of massively superior continual deep learning. And that's what we hope to do in the next couple years. >> Wonderful. Do you think that these algorithms can be applied to the current state of affairs with people scaling LLMs and trying to get them to do continual learning without catastrophic forgetting?
而有了持续反向传播,我们就不断注入一点随机性,一点"生成与测试",一点生成,然后反向传播的运算过程就充当了那个测试者。所以,你需要,你需要那个东西。而且如果你能把这些很好地结合起来,我认为你就会得到新一代的、性能大幅超越的持续深度学习。这就是我们希望在未来几年里做到的事。>> 太好了。你认为这些算法能不能用到现在的局面上?现在大家都在扩展大语言模型,试图让它们做到持续学习而不发生灾难性遗忘。
便签引用
42:22
>> Yeah, absolutely. I think it's So, I don't think that you could take an existing model and say I'm going to just start updating it with these algorithms because these algorithms meta learn how to learn. So, really you have to say, I'm going to learn from scratch. So, let's say I learn a new foundation model, but I'm going to learn with this these new algorithms. These new algorithms in addition to learning the knowledge, they're also going to learn how to learn future things. So, they're learning two things at the same time. And then um then I think you would be able to learn new things without catastrophic forgetting.
>> 是的,绝对可以。我觉得……不过,我不认为你可以拿一个现成的模型,然后说我要直接开始用这些算法去更新它,因为这些算法是在元学习「如何学习」。所以你真的得说,我要从头开始学。也就是说,比方说我训练一个新的基础模型,但我要用这些新算法来学。这些新算法除了学习知识之外,还会学习如何去学未来的东西。所以它们是同时在学两样东西。然后,嗯,我认为那样你就能学到新东西而不会发生灾难性遗忘。
便签引用
42:57
>> the most radical thing in that you're trying to do in your company in terms of from the current state of affairs to try to do these two things at the same time? >> Most radical thing. >> Is I think that's >> This goes back to I'm not crazy, everyone else is crazy. >> [laughter] >> Yeah. >> That's perhaps not totally radical. There was a point in like 2016 to 2018 where a lot of people were exploring these ideas quite a bit. They were doing it in a much more limited setting. So, they would say, we have a distribution of problems and then in this specific case we'll do it whereas we want to do it from a single stream of experience. So, our method should be more generally applicable. So, I think many people have explored this, but no one has explored this in the general setting where the resulting algorithm would be applicable everywhere.
>> 从目前的现状来看,你在自己公司里想做的最激进的事情,就是同时做到这两件事吗?>> 最激进的事情。>> 我觉得那就是……>> 这又回到那句话了:我不疯,是其他人疯了。>> [笑] >> 是啊。>> 那也许并不算完全激进。大概在 2016 到 2018 年那段时间,很多人都相当深入地探索过这些想法。只不过他们是在一个受限得多的设定下做的。他们会说,我们有一个问题分布,然后在这个特定情形下我们来做这件事;而我们想做的是从单一的经验流中学习。所以,我们的方法应该更具普遍适用性。所以我认为很多人探索过这个方向,但没有人在通用设定下探索过——在那种设定里,得到的算法可以到处适用。
便签引用
1020 瓦万亿参数与行业的局部极小值
43:43
>> So, what would be the most radical thing that your company your new company is trying to do that other people are not doing? >> What's the most ambitious thing? Remember, I don't think I'm weird, so I don't want to say it's radical. >> the most ambitious >> ambitious thing, I think is to try to have the full spectrum of knowledge both about the tiny things and about the big things. You know, like thinking about how you take an airplane from one city to another. That's a a very big thing. You know, it's it's more it's like your your space flight example, but it's just kind of more common sensical to think about cuz we all many of us take airplanes and any all of us use abstractions on all kinds of our life. And even even the squirrels use abstractions. So, to have that spectrum of of knowledge uh from the small to the big and to treat it in a uniform way and to be able to help have it self uh maintaining. You know, the big question is always you have your knowledge-based system and what keeps the knowledge in
>> 那么,你的公司、你的新公司想做而别人没有在做的最激进的事情是什么?>> 最有雄心的事情是什么?记住,我不觉得自己奇怪,所以我不想说它是激进的。>> 最有雄心的……>> 最有雄心的事情,我认为是试图拥有全谱系的知识,既包括细小的事物,也包括宏大的事物。你知道,比如思考你怎么坐飞机从一个城市到另一个城市。那是一件非常大的事。你知道,这更像是你说的那个太空飞行的例子,只不过它更符合常识、更容易想象,因为我们很多人都坐过飞机,而我们所有人在生活的方方面面都在使用抽象。甚至连松鼠也在用抽象。所以,要拥有那种从小到大的知识谱系,并以统一的方式来处理它,并且能让它自我维护。你知道,最大的问题始终是:你有一个基于知识的系统,那是什么在保证里面的知识是正确的?
便签引用
44:49
it correct? Well, what keeps the knowledge correct in a large language model is well, people did a lot of post-training and and they they they made it sure it was correct. And then they freeze it after that. So, that's what keeps it correct. But really our minds, we are we're always changing things and yet something keeps it organized and coherent and and and settling back into a good place rather than drifting off into crazy land. That is an I think our our biggest ambition to have a mind that is self-consistent and and can keep training itself and making it coherent.
那么,在大语言模型里,是什么在保证知识正确呢?是人们做了大量的后训练,他们确保了它是正确的。然后在那之后就把它冻结了。所以,就是这个在保证它的正确性。但实际上我们的头脑,我们一直在改变东西,然而总有某种机制让它保持有条理、连贯,并且回落到一个良好的状态,而不是飘到疯狂的世界里去。我认为那是我们最大的雄心:拥有一个自洽的心智,它能持续训练自己,并保持连贯。
便签引用
45:26
>> that. Can I ask? It almost seems that it's it's such a ambitious vision and the idea that all these things can be unified into a single mind is so ambitious. >> It's within reach. I think it's within reach. It's here it's 2026 and our computers are so fast. You know, is it is it so ambitious that it's out of reach? Uh or or do we have already inklings of how all the steps can be done? And we I I think we have a vision and inklings. Um I don't think it's I don't think it's inappropriate. >> Your vision involves a trillion parameter model with 20 watts.
>> 嗯。我能问一下吗?这看上去几乎是一个如此有雄心的愿景,而且把所有这些东西统一到一个单一心智里的想法,实在太有雄心了。>> 它是触手可及的。我认为它是触手可及的。现在是 2026 年,我们的计算机这么快。你知道,它真的雄心大到遥不可及吗?呃,还是说我们其实已经对每一步该怎么做有了一些眉目?我认为我们有一个愿景,也有一些眉目。嗯,我不认为这是不切实际的。>> 你的愿景包括一个万亿参数的模型,只用 20 瓦。
便签引用
46:07
That seems pretty ambitious. >> That is ambitious. Uh, in some sense with current technology, I would say it's also impossible. Like just storing a trillion parameters in memory would probably use more than 20 watts of energy with current memory technologies, but we are really thinking of okay, things are getting better, computation is getting cheaper or it is getting more energy efficient. So, where would be would be in 5 to 10 years? And I think 5 to 10 years with the right algorithms and we can totally be in a world where this would be possible.
那听起来相当有雄心。>> 那确实有雄心。呃,从某种意义上说,以当前的技术,我会说这也是不可能的。比如说,光是把一万亿个参数存在内存里,按现在的存储技术,可能就要消耗超过 20 瓦的能量;但我们真正想的是,好,事情在变好,计算在变便宜,或者说变得更加节能。那么 5 到 10 年后会是什么样?我认为 5 到 10 年后,配上正确的算法,我们完全可能处在一个让这件事成为可能的世界里。
便签引用
46:43
>> So, 5 to 10 years is two orders of magnitude of Moore's law. It's a standard improvement. If we double every 18 months, 10 years would give you two orders of magnitude. And so, for Kurzweil's statement to be plausible, then today you should be able to do it for for what? 20 watts? Two orders of magnitude? >> 2,000 >> 2,000 watts. If you can do it with 2,000 watts today, yeah, then in 10 years you'll be able to do it for 20 watts. >> You think you can do it for a 2,000 watts? You have I think lots of people at research labs that have access to way more than that.
>> 那么,5 到 10 年就是摩尔定律的两个数量级。这是一个标准的进步幅度。如果我们每 18 个月翻一番,10 年就能带来两个数量级。所以,要让库兹韦尔的说法站得住脚,那今天你应该能用多少瓦做到?20 瓦乘以两个数量级?>> 2000 瓦?>> 2000……>> 2000 瓦。如果你今天能用 2000 瓦做到,是的,那 10 年后你就能用 20 瓦做到。>> 你觉得你能用 2000 瓦做到吗?我想很多研究实验室里的人手上的资源可远远不止这些。
便签引用
47:21
>> Yeah, I think we can can be more efficient than that even now with the right algorithm. >> If we can be more efficient than that, then why aren't we? It's not like people just want to spend all their money on spend all their money. >> Sometimes it seems like they >> I'll pay money. >> Sometimes it [laughter] seems like they want to. >> Yeah, I I >> Doesn't it? I think that's how they show they're they're real men by using lots of energy. >> At least when I look at different research groups, I don't even see anyone believing in that it's possible. And I think if you don't believe in it, you're just not going to work on the technical problems and work through them.
>> 是的,我认为有了正确的算法,即便是现在我们也能比那更高效。>> 如果我们能比那更高效,那为什么我们没有做到?大家又不是就想把所有的钱都花在……把所有的钱都花光。>> 有时候看起来他们……>> 我愿意花钱。>> 有时候 [笑] 看起来他们就是想这么干。>> 是啊,我……>> 难道不是吗?我觉得那是他们证明自己是真汉子的方式——靠消耗大量能源。>> 至少当我去看不同的研究团队时,我甚至没看到有人相信这是可能的。而我认为,如果你不相信它,你就根本不会去攻克那些技术问题、把它们一个个解决掉。
便签引用
47:56
>> Is it that it's not possible or it's that there's so much waste in the system? Like one which one is it? Like is it is is there someone who knows how to do it efficiently? >> Yeah. >> And then there's 10 times the number of people in the same lab doing all these other things. And so nine out of 10 people are wasting >> In some sense I the way I think about it is that we are stuck in a local minimum. So, if we want to move towards these new kind of algorithms, it is almost impossible that things will not get worse before they get better.
>> 那到底是它做不到,还是说系统里存在大量浪费?到底是哪一种?比如说,是不是有人其实知道怎么高效地做?>> 嗯。>> 然后同一个实验室里有 10 倍数量的人在做其他各种事情。所以十个人里有九个在浪费……>> 从某种意义上说,我的看法是我们卡在了一个局部极小值里。所以,如果我们想转向这类新算法,那几乎不可能不出现「先变差、后变好」的情况。
便签引用
48:27
So, when we start exploring these new directions, you're not going to get state of the art performance from day one, but it is because it is a different paradigm. Um but that path leads to similar performance at a higher energy scale. And these big labs, they are so locked into a product that they like it is not possible for them to pursue a path where things get worse first. >> Because their current paradigm allows them to keep scaling and this new paradigm they have to take a bet. And then >> And they have to figure out some some technical things that are difficult that we have thought about it for many years.
所以当我们开始探索这些新方向时,你不可能从第一天起就拿到最先进的性能,但那是因为这是一个不同的范式。嗯,但那条路会在更高的能量规模上通向相近的性能。而这些大实验室,他们被产品绑得太死了,以至于他们根本不可能去走一条先变差的路。>> 因为他们当前的范式让他们可以继续扩展,而这个新范式他们得下一个赌注。然后……>> 而且他们还得搞定一些困难的技术问题,这些问题我们已经思考了很多年。
便签引用
11Oak Lab 的愿景与小团队策略
49:03
We know people who have thought about these things for many years and when I talk to them, it makes sense that it's doable, but you need to think about those challenges for a long period of time. >> So, if everything goes right with Oak, what happens with the company? What do you what kind of company are you building? >> Uh if everything goes right, we uh implement the architecture, we can have a genuine uh continual learning and we can form abstractions so that we can do planning and reasoning and and we have so sort of like true intelligence. And then, you know, it's hard to imagine just exactly what will happen by then.
我们认识一些思考这些问题很多年的人,当我跟他们交流时,我觉得这事儿是可行的,但你需要长时间地去琢磨那些挑战。>> 那么,如果 Oak 一切顺利,公司会变成什么样?你在打造一家什么样的公司?>> 呃,如果一切顺利,我们实现了这个架构,我们就能拥有真正的持续学习,而且我们能形成抽象,从而进行规划和推理,我们就有了某种意义上的真正智能。然后,你知道,很难想象到那时究竟会发生什么。
便签引用
49:40
But I think >> Humans will become irrelevant. >> I I don't think that's true at all. I I I >> We don't either. >> I think the world becomes exciting and even more exciting and interesting and and for humans. But in particular, I think there are the You have to wonder about the large language models. They might be at risk. Uh when this eventually happens, you know, I'm sure they'll get a good run. They've already had a good run. You know, they've been very successful. And let me say, just for for clarity that uh large language models are an amazing scientific breakthrough, a breakthrough in the skillful use of language by neural networks, wholly unanticipated.
但我认为……>> 人类会变得无关紧要。>> 我完全不认为是那样。我……>> 我们也不这么认为。>> 我认为世界会变得令人兴奋,甚至对人类来说更加令人兴奋、更有意思。但特别是,我认为……你不得不为大语言模型担心一下。它们可能会面临风险。呃,当这一切最终发生的时候,你知道,我相信它们已经有过一段风光。它们已经风光过了。你知道,它们非常成功。而且请允许我澄清一点:大语言模型是一项了不起的科学突破,是神经网络在娴熟运用语言方面的突破,完全出乎意料。
便签引用
50:22
You know, it was a It was always a hold out for uh symbolic methods in language, and they They have totally changed how that's thought about now. Yeah. It's a It's a big breakthrough. It's so It's frustrating to me that we have to you know, just celebrate that we've made this great progress in the sub subset of the problem of AI, and enjoy that. Instead, it has to pretend to be all of AI. All of intelligence is not fluid, capable use of language. There's so much more. It's an important part. You know, it's like 20% or a quarter of intelligence. There's There's more.
你知道,语言一直是符号方法的最后一块阵地,而它们彻底改变了现在人们对这件事的看法。是的,这是一个重大突破。让我感到沮丧的是,我们本可以就为我们在 AI 这个问题的一个子集上取得的巨大进展而庆祝、享受这份成果。可结果它非得假装自己就是 AI 的全部。智能的全部并不等于流畅、娴熟地运用语言。还有太多别的东西。它是重要的一部分。你知道,大概占智能的 20% 或四分之一。还有更多的东西。
便签引用
50:59
>> Yeah. >> We're not done. >> Yeah. If everything goes right, are you imagining that there's a single minds that can do everything from learn how to swing from tree branches to make a spaceship, uh to you know, all these various things we've talked about today. Is it a single mind, and is it a single set of weights that can that can do all these things, or is it >> It's a single design. >> Okay. >> And there'll be many different There'll be many minds. >> Mm. Okay. So, it's a single design that reacts to different environments.
>> 是啊。>> 我们还没有完成。>> 是啊。如果一切顺利,你设想的是有一个单一的心智,能做到从学会在树枝间荡秋千,到造一艘宇宙飞船,呃,到今天我们聊到的所有这些形形色色的事情。它是一个单一的心智吗?是不是一套权重就能做所有这些事情,还是说……>> 它是一个单一的设计。>> 好的。>> 而会有很多不同的……会有很多个心智。>> 嗯。好的。所以它是一个单一的设计,对不同的环境作出反应。
便签引用
51:30
>> And it did it And different versions of that mind would learn different things because they have different experience. This sort of goes back to the big world hypothesis that there are infinitely many things to learn, so one system cannot learn infinitely many things. And like I think Rich already mentioned this, but if you have two of these systems, if you have two of the largest systems in the world, then it is trivial that they cannot model each other because they are equally complex. So, single system would never be able to get to a point where it can learn everything. It would always be multiple systems that are learning from their own experience.
>> 而且那个心智的不同版本会学到不同的东西,因为它们有不同的经验。这某种程度上又回到了大世界假说:要学的东西有无穷多,所以一个系统无法学习无限多的东西。而且我想 Rich 刚才已经提到过这一点,但如果你有两个这样的系统,如果你有世界上最大的两个系统,那么很显然它们无法相互建模,因为它们的复杂度是相当的。所以,单个系统永远不可能达到能学会一切的地步。永远都会是多个系统各自从自己的经验中学习。
便签引用
52:03
>> Guys, are you hiring? What kind of people are you looking for? >> We are hiring. The initial team, most of it we already have in our mind. So, these are people who have thought about these ideas in the past in many uh you know, for a long time. And we are going to take a slightly different approach because this is a different paradigm. It doesn't make sense to become large very quickly because uh in some sense, everyone we hire has to uh come to see what we see. And not everyone sees that. So, we're going to start small, slowly grow to maybe a handful or two or three uh and then go from there.
>> 各位,你们在招人吗?你们在找什么样的人?>> 我们在招人。最初的团队,大部分人选我们心里已经有数了。这些人都是过去就思考过这些想法的人,在很多方面、而且思考了很长时间。我们会采取一种略有不同的做法,因为这是一个不同的范式。很快把规模做大是没有意义的,因为某种意义上说,我们招的每个人都得能看到我们所看到的东西。而并不是每个人都能看到。所以我们会从小做起,慢慢增长到大概几个人、两三个人,然后再往下走。
便签引用
52:40
>> We want to be super aligned. >> We want to be super aligned. >> So, that we can be um very productive working together and and scaling the progress. >> Absolutely. >> Very, very cool. >> Wonderful. I love this conversation. Thank you for taking the time to share what you're up to. You are, you know, an an unusually deep thinker about where reinforcement learning and algorithmic design will go. And it was a true pleasure to get to explore it together with you today. So, thank you. >> Thank you very much. Thank you. It's our pleasure.
>> 我们希望高度一致。>> 我们希望高度一致。>> 这样我们才能一起非常高效地工作,并把进展规模化。>> 完全同意。>> 非常非常酷。>> 太好了。我很喜欢这次对话。谢谢你们抽时间来分享你们正在做的事。你们对强化学习和算法设计的走向有着非同寻常的深刻思考。今天能和你们一起探讨这些,真的非常荣幸。所以,谢谢你们。>> 非常感谢。谢谢。这是我们的荣幸。
便签引用
53:15
>> [music]
>> [音乐]
便签引用
53:21
[music]
[音乐]
便签引用
53:37
[music]
[音乐]
便签引用
视频总结 · 一句话概括与核心要点

一句话概括

Rich Sutton 与 Khurram Javed 认为当前 LLM 范式的根本缺陷在于"部署后权重冻结、停止学习",其新公司 Oak Lab 要用步长元学习、生成—测试(continual backprop)等算法实现从单一经验流出发的持续深度学习与自发抽象,并据此规划与推理。

核心要点

  • "持续学习"本就是学习的常态,冻结权重才是反常。 Sutton 强调 AI 热潮之前没人需要说"continual learning",因为一切学习都是持续的;如今 LLM 在交互中"权重绝对不变",却宣称拥有博士级专业能力,他认为"不是我怪,是这个领域怪"。
  • 《苦涩的教训》26 字版:别被人类知识分心,专注随算力扩展的方法(搜索与学习)。 它反对的不是先验知识本身(文中开头就说先验与学习"应是朋友"),而是实践中人们偏爱既有知识而贬低学习;需要的是"能随算力扩展的精巧算法",而非随人力投入扩展。
  • LLM 是苦涩教训的正反两面例证。 正面:它用可扩展方法"喝干互联网"获得巨大能力;反面:互联网有限而世界远大于互联网,最终仍被依赖人类知识所限制。Sutton 称 LLM 是"语言的重大科学突破,完全出乎意料",但语言只占智能的约 20%–25%,"我们还没完成"。
  • 合成数据是"大错误",因为它被人类专家瓶颈化。 Javed 的论证:若所有实验室工程师都去度假,谁来生成合成数据?以回声定位无人机为例,必须先有领域专家决定什么数据是对的;自动驾驶的仿真同样依赖大量工程师反复修补 sim-to-real 差距。Sutton 补充:任何仿真相对真实世界都是"微观的",比如无法为"他人此刻在想什么"生成合成数据。
  • "大世界假说"是持续学习的理论根基。 世界比任何智能体复杂得多(因其包含众多其他智能体),所以不可能有最优解,只能用严重近似;智能体必须针对它所处的那一小块世界持续调整近似。推论:两个同等复杂的顶级系统互相无法建模,因此永远不会有"一个学会一切的单一系统",而是同一设计的多个心智各自积累不同经验。
  • 动物不做监督学习,学校是智能本质之外的特例。 没人能示范"肌肉该如何抽动",别人发 Paris 音的肌肉动作放到你身上会发出不同声音——目标只能由自身经验获得。松鼠能突破任何障碍进入喂鸟器、实时化解跌落,Sutton 认为人与动物只是程度之差,强调差异是"傲慢"。但他同意人类需要想象与规划,文化传承极其重要,两者"不该被当成敌人"。
  • 领域最大的空白:学到模型,再用模型规划。 AlphaGo 与数学证明(Lean)之所以可行是因为模型已知;而"自发抽象 + 学习抽象模型 + 用它规划"的能力在现有系统中完全缺失。范式转移(如爱因斯坦)正是人在积累知识后从经验中构建新抽象并规划的结果,这一技能既能在人类知识边缘研究,也能在感知—运动流层面研究。
  • 灾难性遗忘"完全可治",解法是两项算法。 其一,步长优化:每个权重有独立的元学习步长,多数权重步长极小,新样本只改动该改的位置;其二,特征空间的生成—测试:不依赖缓慢的梯度,持续注入随机初始化的新单元,由反向传播充当"测试者"——这就是他们发在 Nature 上的 continual backprop。Cursor 的 tab 模型虽会更新权重,但靠成千上万用户的批数据做一次更新,无法让单个用户教自己的模型。
  • 这些算法不能嫁接到现有模型上,必须从头训练。 因为它们同时学"知识"和"如何学未来的知识"(元学习),需要用新算法重新训练基础模型。2016–2018 年曾有人在"问题分布"设定下探索过,但没人做过单一经验流的通用版本。
  • 大实验室困在局部最优,Oak 选择"先变差再变好"的路。 新范式一开始不会有 SOTA 表现,被产品锁定的大厂无法承受这条路;Javed 观察到各研究组甚至"没人相信这是可能的",不相信就不会去解技术难题。

结论与值得注意的细节

  • Oak Lab 的最高野心:一种统一处理从微小到宏大(从肌肉抽动到"坐飞机跨城")全谱知识、能自我维持一致性的心智——LLM 靠后训练加冻结来"保持正确",而真实心智是不断改变却仍能"回到好的状态而不漂向疯狂"。Sutton 认为这"在可及范围内",2026 年算力已足够。
  • 能耗目标:万亿参数、20 瓦。Javed 承认以现有内存技术仅存储万亿参数就超过 20 瓦,寄望 5–10 年(约两个数量级摩尔定律);主持人反推今天须能以 2000 瓦实现,两人表示用对算法可以更高效,Sutton 调侃大厂烧能源是"证明自己是真男人"。
  • 若成功,Sutton 不认为人类会无关紧要,反倒是"LLM 可能有风险"——它们已经"跑得不错了"。
  • 招聘策略:初始团队心中已有人选,多为长期思考这些问题的人;刻意不快速扩张,先做到"极度对齐"的一小撮人再增长。
  • 背景细节:Sutton 2003 年在 AI 寒冬、身患癌症"尝试死亡多年未遂"的情况下去了阿尔伯塔,把坚持研究归因于富兰克林所谓"习惯或虚荣"中的习惯;Javed 从未申请过做他的学生,是合作六个月后自然转成论文选题;Alberta Plan 12 步中第 2 步"持续深度学习"被视为解锁一切的关键,后半程则关于让智能体在所处世界中学到正确抽象。

核心句型 · 9
1. It's not that …, it's just that …
“I'm not weird. The field is weird.”
用对比结构把「异常」重新归属。适合反驳时把问题从自己身上转移到环境或行业上,语气斩钉截铁,口语中常配停顿。
2. It wouldn't make any sense to talk about X that wasn't Y
“It wouldn't make any sense to talk about learning that wasn't continual”
通过「谈论一个不 Y 的 X 没有意义」来主张 Y 是 X 的内在属性。适合定义之争,仿写:It wouldn't make sense to talk about science that wasn't empirical.
3. What else are you going to do?
“What else you going to do?”
反问式回答,表示选择是理所当然的。用于回应「为什么坚持」类问题,显得轻松而笃定。
4. It's both a positive example and a negative example of …
“It's both a positive example and a negative example of the big lesson”
用「既是正例又是反例」框架对复杂现象做双面评价,避免非黑即白。学术讨论中很实用。
5. If all the X went on vacation, who would …?
“If all the engineers … went on vacation, who would generate the synthetic data?”
思想实验式反驳:假设去掉某一角色,看系统能否运转,从而暴露隐藏依赖。仿写:If all the editors left, who would decide what's true?
6. Doesn't matter how much …, it will not allow you to … without …
“Doesn't matter how much synthetic data you generate … it will not allow you to do that task without humans figuring it out first.”
「无论多少……都不能……除非……」用于说明数量无法替代某个必要条件。省略主语 It 是口语特征。
7. There's no reason in principle why X has to be opposed to Y
“There's no reason in principle why these have to be opposed.”
「原则上没有理由必须对立」,用于调和被视作二元对立的概念。in principle 与后文 in practice 对举效果更佳。
8. It is almost impossible that things will not get worse before they get better
“It is almost impossible that things will not get worse before they get better”
双重否定强调「先坏后好」几乎必然。适合描述转型期、范式切换的代价。
9. You have to wonder about X. They might be at risk.
“You have to wonder about the large language models. They might be at risk.”
「你不得不为 X 担心」,委婉表达对某事物前景的怀疑,比直接说 X will fail 更克制。
词汇精讲 · 124 · 按出现顺序
radical /ˈrædɪkl/ adj. 0:00
激进的,根本性的
seminal /ˈsemɪnl/ adj. 0:59
开创性的,有深远影响的(seminal textbook/paper)
propelling /prəˈpelɪŋ/ v. 0:59
推动,推进(propel the field forward)
set off to phr. 1:28
动身去做,着手做
bastion /ˈbæstʃən/ n. 1:28
堡垒,重镇(比喻某种事物的据点)
in its infancy phr. 1:28
处于初期,尚在萌芽阶段
conviction /kənˈvɪkʃn/ n. 1:28
坚定的信念
doubling down on phr. 2:10
加倍下注于,更坚定地投入
remission /rɪˈmɪʃn/ n. 2:10
(疾病的)缓解期
might as well phr. 2:10
不如,倒不如(表示没有更好选择)
vanity /ˈvænəti/ n. 3:12
虚荣心
Divine intervention /dɪˈvaɪn ˌɪntərˈvenʃn/ n. 3:52
神的干预,天意
perception /pərˈsepʃn/ n. 4:24
感知
motto /ˈmɑːtoʊ/ n. 5:08
座右铭,信条
organically /ɔːrˈɡænɪkli/ adv. 6:10
自然而然地,非刻意安排地
thesis proposal n. 6:40
论文开题报告
tome /toʊm/ n. 7:10
大部头著作,巨著
a long time coming phr. 7:10
酝酿已久,早该到来
symbolic AI n. 7:45
符号主义人工智能(基于规则与逻辑的传统 AI)
essence /ˈesns/ n. 8:28
精髓,本质
tortured /ˈtɔːrtʃərd/ adj. 8:28
(此处)被扭曲的,被曲解的
anticipate /ænˈtɪsɪpeɪt/ v. 9:40
预料,预先想到
drink in phr. 9:40
贪婪地吸收,尽情摄取
finite /ˈfaɪnaɪt/ adj. 10:20
有限的
holds us back phr. 10:20
拖住我们,阻碍我们前进
push on phr. 10:59
(对某观点)追问、施压
synthetic data /sɪnˈθetɪk ˈdeɪtə/ n. 10:59
合成数据(由程序或模型生成的训练数据)
leverages /ˈlevərɪdʒɪz/ v. 10:59
利用,发挥……的作用
floating around phr. 11:33
(想法、传闻)流传,四处传播
hypothesis /haɪˈpɑːθəsɪs/ n. 11:33
假说
bottleneck /ˈbɑːtlnek/ n. 12:17
瓶颈;v. 被卡住(be bottlenecked by)
echolocation /ˌekoʊloʊˈkeɪʃn/ n. 12:45
回声定位
domain experts /doʊˈmeɪn ˈekspɜːrts/ n. 12:45
领域专家
localize /ˈloʊkəlaɪz/ v. 13:35
定位,确定自身位置
friction /ˈfrɪkʃn/ n. 14:53
摩擦力
microscopic /ˌmaɪkrəˈskɑːpɪk/ adj. 14:53
微小的,微不足道的
optimal /ˈɑːptɪməl/ adj. 15:37
最优的
approximations /əˌprɑːksɪˈmeɪʃnz/ n. 15:37
近似,近似值
tuned to phr. 15:37
针对……调校,适配于
argumentative /ˌɑːrɡjuˈmentətɪv/ adj. 16:19
好辩的,爱抬杠的
cohort /ˈkoʊhɔːrt/ n. 16:19
一批人,同期群体
sim-to-real gap n. 16:19
仿真到现实的差距(机器人学术语)
curating /ˈkjʊreɪtɪŋ/ v. 17:10
筛选整理(数据、内容)
leveraging /ˈlevərɪdʒɪŋ/ n. 17:49
利用,借力
triumph /ˈtraɪʌmf/ n. 18:17
胜利,重大成功
priors /ˈpraɪərz/ n. 18:17
先验(知识、假设),机器学习术语
vindicated /ˈvɪndɪkeɪtɪd/ adj. 18:17
被证明正确的,得到平反的
nature and nurture phr. 18:59
先天与后天
affection for phr. 18:59
对……的偏爱、喜爱
dismiss /dɪsˈmɪs/ v. 18:59
否定,不予考虑
expertise /ˌekspɜːrˈtiːz/ n. 20:15
专业知识,专长
drip /drɪp/ v. 20:44
一点一点地注入,滴入
from scratch phr. 21:22
从零开始
zillions of /ˈzɪljənz/ phr. 21:22
无数的,天文数字的(口语夸张)
routing /ˈruːtɪŋ/ n. 22:02
路由,路径选择
contention /kənˈtenʃn/ n. 22:37
论点,主张
in-context learning n. 22:37
上下文内学习(LLM 通过提示中的示例调整行为而不改权重)
pre-training /ˌpriːˈtreɪnɪŋ/ n. 23:40
预训练
policy /ˈpɑːləsi/ n. 24:09
策略(强化学习术语:从状态到动作的映射)
personalization /ˌpɜːrsənələˈzeɪʃn/ n. 24:48
个性化
proprioception /ˌproʊpriəˈsepʃn/ n. 25:28
本体感觉(感知身体位置与姿态的内部感觉)
ingrained /ɪnˈɡreɪnd/ adj. 25:28
根深蒂固的
plastic /ˈplæstɪk/ adj. 25:28
(神经科学)可塑的
supervised learning n. 26:48
监督学习(用带正确答案的样本训练)
twitch /twɪtʃ/ v. 26:48
(肌肉)抽动,收缩
transmission /trænsˈmɪʃn/ n. 27:31
传递,传播
distraction /dɪˈstrækʃn/ n. 28:46
分心之物,干扰
theorems /ˈθiːərəmz/ n. 28:46
定理
paradox /ˈpærədɑːks/ n. 29:25
悖论
vocal cords /ˈvoʊkl kɔːrdz/ n. 30:06
声带
sensory motor /ˈsensəri ˈmoʊtər/ adj. 30:06
感觉运动的
inherently /ɪnˈhɪrəntli/ adv. 30:06
本质上,固有地
abstraction /æbˈstrækʃn/ n. 30:39
抽象;抽象概念
bird feeder /bɜːrd ˈfiːdər/ n. 30:39
喂鸟器
trajectories /trəˈdʒektəriz/ n. 31:14
轨迹,弹道
Breaking a fall phr. 31:14
化解摔倒的冲击
hubristic /hjuːˈbrɪstɪk/ adj. 31:14
傲慢自大的
commonalities /ˌkɑːməˈnælətiz/ n. 31:48
共同点
back up phr. 31:48
支持,声援(某人)
uniquely /juˈniːkli/ adv. 32:25
独一无二地
paradigm shifting /ˈpærədaɪm ˈʃɪftɪŋ/ adj. 33:33
范式转变的,颠覆性的
accumulated /əˈkjuːmjəleɪtɪd/ v. 34:14
积累
generalizes /ˈdʒenrəlaɪzɪz/ v. 35:10
泛化(机器学习:在未见数据上仍表现良好)
counterexample /ˈkaʊntərɪɡˌzæmpl/ n. 35:40
反例
pontificating /pɑːnˈtɪfɪkeɪtɪŋ/ v. 36:23
高谈阔论,武断说教
lamenting /ləˈmentɪŋ/ v. 36:23
哀叹,感慨
crystallize /ˈkrɪstəlaɪz/ v. 36:54
使明确,使具体化
unlocks /ʌnˈlɑːks/ v. 36:54
解锁,开启
conditioned on phr. 38:10
以……为条件(统计/机器学习术语)
niche /nɪtʃ/ adj. 38:10
小众的,专门的
naive /naɪˈiːv/ adj. 38:45
朴素的,未经优化的(算法语境)
Catastrophic forgetting /ˌkætəˈstrɑːfɪk fərˈɡetɪŋ/ n. 40:00
灾难性遗忘(神经网络学新任务时丧失旧知识)
curable /ˈkjʊrəbl/ adj. 40:00
可治愈的,可解决的
step size n. 40:00
步长,学习率
metalearn /ˈmetəlɜːrn/ v. 40:00
元学习(学习如何学习)
generate and test phr. 40:37
生成与测试(先随机提出候选再筛选的方法)
gradients /ˈɡreɪdiənts/ n. 40:37
梯度
sustained /səˈsteɪnd/ adj. 40:37
持续的,持久的
backprop /ˈbækprɑːp/ n. 41:12
反向传播(backpropagation 缩写)
initialized /ɪˈnɪʃəlaɪzd/ v. 41:12
初始化
used up phr. 41:12
用尽,耗尽
injecting /ɪnˈdʒektɪŋ/ v. 41:46
注入
massively superior phr. 41:46
大幅优越的
foundation model n. 42:22
基础模型
generally applicable phr. 42:57
普遍适用的
full spectrum /fʊl ˈspektrəm/ n. 43:43
全谱系,全范围
common sensical adj. 43:43
符合常识的
self maintaining adj. 43:43
自我维护的
coherent /koʊˈhɪrənt/ adj. 44:49
连贯的,自洽的
drifting off phr. 44:49
漂离,逐渐偏离
within reach phr. 45:26
触手可及,可以实现
inklings /ˈɪŋklɪŋz/ n. 45:26
模糊的认识,眉目
orders of magnitude phr. 46:43
数量级
plausible /ˈplɔːzəbl/ adj. 46:43
站得住脚的,貌似合理的
local minimum /ˈloʊkl ˈmɪnɪməm/ n. 47:56
局部极小值(优化术语,比喻困于次优状态)
state of the art phr. 48:27
最先进水平
locked into phr. 48:27
被……锁定,无法脱身
irrelevant /ɪˈreləvənt/ adj. 49:40
无关紧要的
a good run phr. 49:40
一段成功的时期
wholly unanticipated phr. 49:40
完全出乎意料的
hold out n. 50:22
最后的据点,坚守的阵地
fluid /ˈfluːɪd/ adj. 50:22
流畅的
a handful /ˈhændfʊl/ n. 52:03
少数几个
aligned /əˈlaɪnd/ adj. 52:40
目标一致的,步调一致的
精读便签
下载便签 手机:长按图片也可保存
← 上一期 · NO.125Dylan Patel – Two labs will soon control most of the world's workforce 下一期 · NO.127 →He won a Nobel here for AlphaFold. Then he left. - John Jumper
苏菲周报 · THE WEEKLY 每周一封,
追问一个大问题。
苏菲拉底的每周来信,写这一周在追问的问题和看到的回应。
苏菲拉底
ASK THE BIG QUESTIONS · THINK DEEPLY · SEE THE WORLD DIFFERENTLY
苏菲拉底微信公众号二维码 微信公众号
© 2026 苏菲拉底 · 内容仅供学习 [email protected]